<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom"><title type="html">/dev/noah</title><subtitle>Dispatches on IP, systems, and software.</subtitle><link href="https://blog.tilton.co/" rel="alternate" type="text/html"/><link href="https://blog.tilton.co/feed.xml" rel="self" type="application/atom+xml"/><updated>2026-10-08T02:00:36-05:00</updated><id>https://blog.tilton.co/feed.xml</id><entry><title type="html">What Goes On at the Board</title><link href="https://blog.tilton.co/2026/08/04/what-goes-on-at-the-board.html" rel="alternate" type="text/html" title="What Goes On at the Board"/><published>2026-08-04T00:00:00-05:00</published><updated>2026-10-08T02:00:36-05:00</updated><id>https://blog.tilton.co/2026/08/04/what-goes-on-at-the-board</id><content type="html" xml:base="https://blog.tilton.co/2026/08/04/what-goes-on-at-the-board.html"><![CDATA[<blockquote>
<p>&ldquo;What goes on in your mind?&rdquo;
— The Velvet Underground</p>
</blockquote>
<p>The USPTO&rsquo;s <a href="https://data.uspto.gov/home">Open Data Portal</a> API covers a lot
of ground — trademarks, patent examination data, maintenance fees, and more.
This post covers one slice: the appeals, trials, and interferences
endpoints, which return decisions from the Patent Trial and Appeal Board
(formerly the Board of Patent Appeals and Interferences (BPAI)). Making
sense of
that data means knowing what it means, or
at least what it relates to. Here&rsquo;s the quick primer.</p>
<p>The Board runs several different kinds of proceedings, some of which no
longer exist. An applicant&rsquo;s <em>ex parte</em> appeal of the examiner&rsquo;s rejection
has a different procedural origin from a competitor&rsquo;s attempt to
kill an issued patent through <em>inter partes</em> review, even though both end up
before the same
Board. Confusingly, two of those proceeding types — <em>inter partes</em> review
and <em>inter partes</em> reexamination — share half their name while being
procedurally almost nothing alike. I memorized this taxonomy for the patent
bar exam the way you memorize anything for a multiple-choice test — a list
of names and deadlines with no weight behind them. It didn&rsquo;t become real
until I started practicing and looking at the data: who can bring each one,
who decides it, and whether it&rsquo;s still available.</p>
<p>The short version:</p>
<figure class="anchored-table" id="board-proceedings-at-a-glance"><table>
	<thead>
			<tr>
					<th>Proceeding</th>
					<th>Who can bring it</th>
					<th>Decided by</th>
					<th>Still available</th>
			</tr>
	</thead>
	<tbody>
			<tr>
					<td><em>Ex parte</em> appeal</td>
					<td>Applicant</td>
					<td>Board</td>
					<td>Yes</td>
			</tr>
			<tr>
					<td>Interference</td>
					<td>Competing applicant/patentee</td>
					<td>Board</td>
					<td>No — pre-3/16/2013 filings only, shrinking to zero</td>
			</tr>
			<tr>
					<td>Derivation</td>
					<td>Applicant/patent owner alleging theft</td>
					<td>Board</td>
					<td>Yes, rare</td>
			</tr>
			<tr>
					<td><em>Inter partes</em> review (IPR)</td>
					<td>Any third party except the patent owner</td>
					<td>Board</td>
					<td>Yes</td>
			</tr>
			<tr>
					<td>Post-grant review (PGR)</td>
					<td>Any third party except the patent owner, within 9 months of grant</td>
					<td>Board</td>
					<td>Yes, narrow window</td>
			</tr>
			<tr>
					<td>Covered business method review (CBM)</td>
					<td>Third party already sued or charged with infringement</td>
					<td>Board</td>
					<td>No — sunset September 16, 2020</td>
			</tr>
			<tr>
					<td><em>Inter partes</em> reexamination</td>
					<td>Any third party</td>
					<td>Examiner, appealable to Board</td>
					<td>No — requests only 1999–9/15/2012</td>
			</tr>
			<tr>
					<td><em>Ex parte</em> reexamination</td>
					<td>Anyone, including the patent owner</td>
					<td>Examiner, appealable to Board</td>
					<td>Yes</td>
			</tr>
	</tbody>
</table>
<figcaption><a href="#board-proceedings-at-a-glance" aria-label="Link to this table: Board proceedings, who can bring them, and whether they remain available">Board proceedings, who can bring them, and whether they remain available</a></figcaption>
</figure>

<h2 id="the-applicants-appeal"><a class="heading-anchor" href="#the-applicants-appeal" aria-label="Link to this section: The Applicant’s Appeal">##</a>The Applicant&rsquo;s Appeal</h2>
<p><strong><em>Ex parte</em> appeal</strong> happens when an applicant formally appeals the
examiner&rsquo;s rejection to the Board itself. <em>Ex parte</em> here means the only
two parties are the applicant and the examiner, with no adverse third party
— not that the rejection goes uncontested. The Board affirms, reverses,
affirms in part, or remands. You can file petitions, for example
<a href="https://www.uspto.gov/web/offices/pac/mpep/s706.html">to challenge an examiner&rsquo;s premature final rejection</a>.
Some can toll a deadline, too: if the examiner&rsquo;s answer contains an
undesignated new ground of rejection, a petition to have it designated as
new tolls the reply-brief period under
<a href="https://www.ecfr.gov/current/title-37/chapter-I/subchapter-A/part-41/subpart-B/section-41.40">§ 41.40 of title 37 of the Code of Federal Regulations</a>.
You have to file that § 1.181 petition within two months of entry of the
answer and before filing any reply brief. A losing party can optionally
request rehearing, then appeal to the Federal Circuit or file a civil action
under 35 U.S.C. § 145.</p>
<h2 id="when-two-applicants-claim-the-same-invention"><a class="heading-anchor" href="#when-two-applicants-claim-the-same-invention" aria-label="Link to this section: When Two Applicants Claim the Same Invention">##</a>When Two Applicants Claim the Same Invention</h2>
<p><strong>Interference</strong> is the old mechanism for resolving a dispute over who
invented something first, when two parties separately claim substantially
the same invention. It only makes sense under a first-to-invent system,
which the United States abandoned for applications with an effective filing
date on or after March 16, 2013. Older applications can still theoretically
interfere with each other — an interference can run for years — but the
population of eligible cases keeps shrinking toward zero and won&rsquo;t come
back.</p>
<p><strong>Derivation proceeding</strong> is the replacement created by the America Invents
Act (AIA), and it asks a completely different question. Under
first-inventor-to-file (FITF), priority isn&rsquo;t about who invented first
anymore — it&rsquo;s about whether the first person to <em>file</em> stole
the invention from someone else. A derivation petitioner has to be an
applicant or patent owner with a competing claim to the same invention, and
has to allege the earlier filer derived it from them without authorization.
Mere earlier invention isn&rsquo;t a derivation theory; it isn&rsquo;t a theory at all
anymore. Derivation is also genuinely rare, with single digits filed most
years and some years none at all.</p>
<p>Neither of these is a validity challenge in the sense a competitor cares
about. Both are inventorship-priority fights between people who each think
the patent (or application) should belong to them.</p>
<h2 id="the-aia-trials-and-whos-actually-allowed-to-bring-one"><a class="heading-anchor" href="#the-aia-trials-and-whos-actually-allowed-to-bring-one" aria-label="Link to this section: The AIA Trials, and Who’s Actually Allowed to Bring One">##</a>The AIA Trials, and Who&rsquo;s Actually Allowed to Bring One</h2>
<p>The America Invents Act created a new adjudicative animal on September 16,
2012: trial proceedings decided directly by administrative patent judges,
not examiners, with discovery, expert testimony, and oral argument. Three of
the four types are genuine third-party validity challenges, and each one has
a different, specific answer to &ldquo;who can bring this.&rdquo;</p>
<p><strong><em>Inter partes</em> review (IPR)</strong> — anyone except the patent owner can petition,
on novelty or obviousness grounds only (§ 102 or § 103), based only on
patents and printed publications. Timing has real teeth: you can&rsquo;t file
until nine months after grant (or after any post-grant review on the same
patent wraps up), and you&rsquo;re barred if you were served with a complaint
alleging infringement of that patent more than a year before you file (35
U.S.C. § 315(b)). You&rsquo;re also barred if you already filed a declaratory
judgment (DJ) action challenging the patent&rsquo;s validity before petitioning —
a counterclaim doesn&rsquo;t count against you, but a first-filed DJ action does.
You have to disclose real-party-in-interest and privity, specifically so a
company can&rsquo;t dodge the time bar or estoppel by routing the petition through
a shell.</p>
<p><strong>Post-grant review (PGR)</strong> has a much narrower filing window — nine months
from grant or reissue, full stop — but much broader grounds: any invalidity
theory except best mode, including § 101 and § 112, not just patents and
publications. The catch is eligibility, not timing: PGR is only available for
patents examined under first-inventor-to-file, meaning patents with an
effective filing date on or after March 16, 2013. That&rsquo;s why PGR petition
volume has always trailed IPR by orders of magnitude — for years after AIA
trials opened, there simply weren&rsquo;t many FITF patents to challenge yet.</p>
<p><strong>Covered business method review (CBM)</strong> doesn&rsquo;t exist anymore. It was a
transitional program under AIA § 18 with an eight-year sunset built into the
statute itself, and it expired on September 16, 2020. While it was alive, it
had the strictest standing requirement of any AIA trial: the patent had to
claim a &ldquo;covered business method&rdquo; (financial-product-or-service-related,
excluding anything that qualified as a &ldquo;technological invention,&rdquo; a
carve-out that generated its own body of litigation about where the line
sat), and — unlike IPR or PGR — the petitioner had to have actually been sued
or charged with infringement of that specific patent. You couldn&rsquo;t
pre-emptively challenge a CBM patent the way you can with IPR. You had to
already be in a real fight over it.</p>
<p><strong>Derivation</strong> also counts as one of the four AIA trial types, even
though — as covered above — it isn&rsquo;t a validity challenge at all.</p>
<h2 id="the-other-reexam-why-review-and-re-exam-arent-the-same-word-twice"><a class="heading-anchor" href="#the-other-reexam-why-review-and-re-exam-arent-the-same-word-twice" aria-label="Link to this section: The Other Reexam: Why “Review” and “Re-exam” Aren’t the Same Word Twice">##</a>The Other Reexam: Why &ldquo;Review&rdquo; and &ldquo;Re-exam&rdquo; Aren&rsquo;t the Same Word Twice</h2>
<p><em>Inter partes</em> review and <em>inter partes</em> reexamination share a name and almost
nothing else, and I think the naming similarity is the single biggest source
of confusion in this whole area.</p>
<p><strong><em>Inter partes</em> reexamination</strong> was created by the American Inventors
Protection Act of 1999, available for requests filed between November 29,
1999, and September 15, 2012 — a hard cutoff, not a phase-out, though
requests already pending on that date kept running under the old rules for
years afterward. The grounds are the same as IPR would later adopt — patents
and printed publications only — and a third-party requester stays involved
throughout the proceeding, which is what makes it <em>inter partes</em>. But
procedurally, it&rsquo;s an <em>examination</em>: it runs in front of an examiner in the
Central Reexamination Unit, not administrative patent judges, and it&rsquo;s
appealable to the Board the same way an ordinary prosecution rejection is.
IPR is <em>inter partes</em> reexamination&rsquo;s direct doctrinal successor — same
requester eligibility concept, same evidentiary scope — redesigned as a trial
decided by the Board itself from day one, instead of an examination that
merely ends up at the Board on appeal.</p>
<p><strong><em>Ex parte</em> reexamination</strong> is older still — it&rsquo;s existed since 1981 and,
unlike <em>inter partes</em> reexam, it&rsquo;s still available today. Anyone can request
one, including the patent owner, and the requester can stay anonymous. But
once the reexamination starts, a third-party requester is cut out of
further participation. There&rsquo;s no adversary left in the room after that
point, which is the <em>ex parte</em> half of the name.</p>
<p>Both reexam types get their own control-number series distinct from ordinary
application numbers: 90-series for <em>ex parte</em> reexam, 95-series for <em>inter
partes</em> reexam, and a 96-series added later for reexaminations ordered out of
supplemental examination proceedings under 35 U.S.C. § 257. If you ever see
one of those control numbers in what looks like an ordinary appeal record,
that&rsquo;s why.</p>
<h2 id="bpai-to-ptab-is-a-rename"><a class="heading-anchor" href="#bpai-to-ptab-is-a-rename" aria-label="Link to this section: BPAI to PTAB Is a Rename">##</a>BPAI to PTAB Is a Rename</h2>
<p>The <strong>Board of Patent Appeals and Interferences (BPAI)</strong> existed from 1982,
when the Federal Courts Improvement Act merged the old Board of Appeals and
Board of Patent Interferences, until September 15, 2012. It heard <em>ex parte</em>
appeals, interferences, and — starting in 1999 — <em>inter partes</em> reexamination
appeals.</p>
<p>On September 16, 2012, the AIA renamed and reconstituted it as the <strong>Patent
Trial and Appeal Board (PTAB)</strong>. Same institution, continuous jurisdiction
over <em>ex parte</em> appeals and interferences, plus the brand-new original trial
jurisdiction over IPR, PGR, CBM, and derivation. &ldquo;BPAI decision&rdquo; and &ldquo;PTAB
decision&rdquo; describe the same body across a name change, with September 16,
2012 as the real dividing line for what <em>kind</em> of new proceeding could be
filed on any given day.</p>
]]></content><author><name>Noah K. Tilton</name></author><category term="patents"/><category term="ptab"/><category term="uspto"/><category term="procedure"/><summary type="html"> “What goes on in your mind?” — The Velvet Underground
The USPTO’s Open Data Portal API covers a lot of ground — trademarks, patent examination data, maintenance fees, and more. This post covers one slice: the appeals, trials, and interferences endpoints, which return decisions from the Patent Trial and Appeal Board (formerly the Board of Patent Appeals and Interferences (BPAI)). Making sense of that data means knowing what it means, or at least what it relates to. Here’s the quick primer.</summary></entry><entry><title type="html">Rotating a USPTO API Key Requires Sending an Email</title><link href="https://blog.tilton.co/2026/07/23/rotating-a-uspto-api-key-requires-sending-an-email.html" rel="alternate" type="text/html" title="Rotating a USPTO API Key Requires Sending an Email"/><published>2026-07-23T00:00:00-05:00</published><updated>2026-07-27T01:11:15-05:00</updated><id>https://blog.tilton.co/2026/07/23/rotating-a-uspto-api-key-requires-sending-an-email</id><content type="html" xml:base="https://blog.tilton.co/2026/07/23/rotating-a-uspto-api-key-requires-sending-an-email.html"><![CDATA[<h2 id="background"><a class="heading-anchor" href="#background" aria-label="Link to this section: Background">##</a>Background</h2>
<p>While reviewing old automation, I checked how the USPTO Open Data Portal handles
API-key rotation. Account holders rotate keys during scheduled maintenance,
after rebuilding an application, when operators change, or after a possible
leak. A routine rotation has three steps: create a replacement key, update the
application, and deactivate the old key.</p>
<p>The USPTO, however, <em>requires an email to be sent</em>. Its
<a href="https://data.uspto.gov/support/faq">FAQ</a> says:</p>
<blockquote>
<p>Can I have multiple API keys with one ID.me account?</p>
<p>No. The ID.me account integration with your USPTO.gov account is a one-to-one connection. You can only integrate your ID.me account into one USPTO.gov account. <em>If you need to replace your API Key, email <a href="mailto:data@uspto.gov">data@uspto.gov</a> a request for a new API Key <a href="https://help.id.me/hc/en-us/articles/4412245504407-USPTO-and-ID-me">https://help.id.me/hc/en-us/articles/4412245504407-USPTO-and-ID-me</a> on your personal Manage API Key page.</em></p>
</blockquote>
<p>The portal includes a self-service control for deactivating the current key.</p>
<h2 id="problem"><a class="heading-anchor" href="#problem" aria-label="Link to this section: Problem">##</a>Problem</h2>
<p>ID.me links one human identity to one USPTO.gov account. The FAQ treats that
identity link as a reason to limit the user to one API key. Several applications
may depend on the same account, and each application may require independent key
rotation or deactivation. The one-key policy and email-only replacement process
are crazy.</p>
<p>The one-key policy forces a choice between failed requests and continued use of
a possibly leaked key. Deactivating the current key immediately causes
authenticated requests to fail until the USPTO issues a replacement key and the
user installs the new key. Keeping the current key active avoids failed requests
while leaving the possibly leaked credential usable. The FAQ gives no turnaround
time for a replacement request.</p>
<p>The email-only replacement process discourages routine rotation. Leaving the
current key alone avoids administrative delay and failed requests. The path of
least resistance is to keep using the same credential until a suspected
compromise forces a change.</p>
<h2 id="solution"><a class="heading-anchor" href="#solution" aria-label="Link to this section: Solution">##</a>Solution</h2>
<p>The portal should let users create multiple named keys and show each key&rsquo;s
creation date, last use, and expiration date. Overlapping keys let users update
each application before deactivating the old key.</p>
<h2 id="closing"><a class="heading-anchor" href="#closing" aria-label="Link to this section: Closing">##</a>Closing</h2>
<p>On July 23, the USPTO announced a <a href="https://www.uspto.gov/about-us/news-updates/uspto-unveils-new-improved-homepage-design">new homepage
design</a>.
The director praised the &ldquo;extensive time and effort&rdquo; spent improving navigation.
I&rsquo;m glad the USPTO got its fancy new splash page. I would trade a little of
that effort for a <code>Create replacement key</code> button.</p>
]]></content><author><name>Noah K. Tilton</name></author><category term="patents"/><category term="uspto"/><category term="security"/><category term="data"/><category term="software"/><summary type="html">##Background While reviewing old automation, I checked how the USPTO Open Data Portal handles API-key rotation. Account holders rotate keys during scheduled maintenance, after rebuilding an application, when operators change, or after a possible leak. A routine rotation has three steps: create a replacement key, update the application, and deactivate the old key.
The USPTO, however, requires an email to be sent. Its FAQ says:
Can I have multiple API keys with one ID.me account?</summary></entry><entry><title type="html">Return of the Vibe Drafter: A MAVENS Stack for Patent Practitioners</title><link href="https://blog.tilton.co/2026/04/01/return-of-the-vibe-drafter-a-mavens-stack-for-patent-practitioners.html" rel="alternate" type="text/html" title="Return of the Vibe Drafter: A MAVENS Stack for Patent Practitioners"/><published>2026-04-01T00:00:00-05:00</published><updated>2026-07-24T10:55:39-05:00</updated><id>https://blog.tilton.co/2026/04/01/return-of-the-vibe-drafter-a-mavens-stack-for-patent-practitioners</id><content type="html" xml:base="https://blog.tilton.co/2026/04/01/return-of-the-vibe-drafter-a-mavens-stack-for-patent-practitioners.html"><![CDATA[<h2 id="introducing-the-mavens-stack"><a class="heading-anchor" href="#introducing-the-mavens-stack" aria-label="Link to this section: Introducing the MAVENS Stack">##</a>Introducing the <strong>MAVENS</strong> Stack</h2>
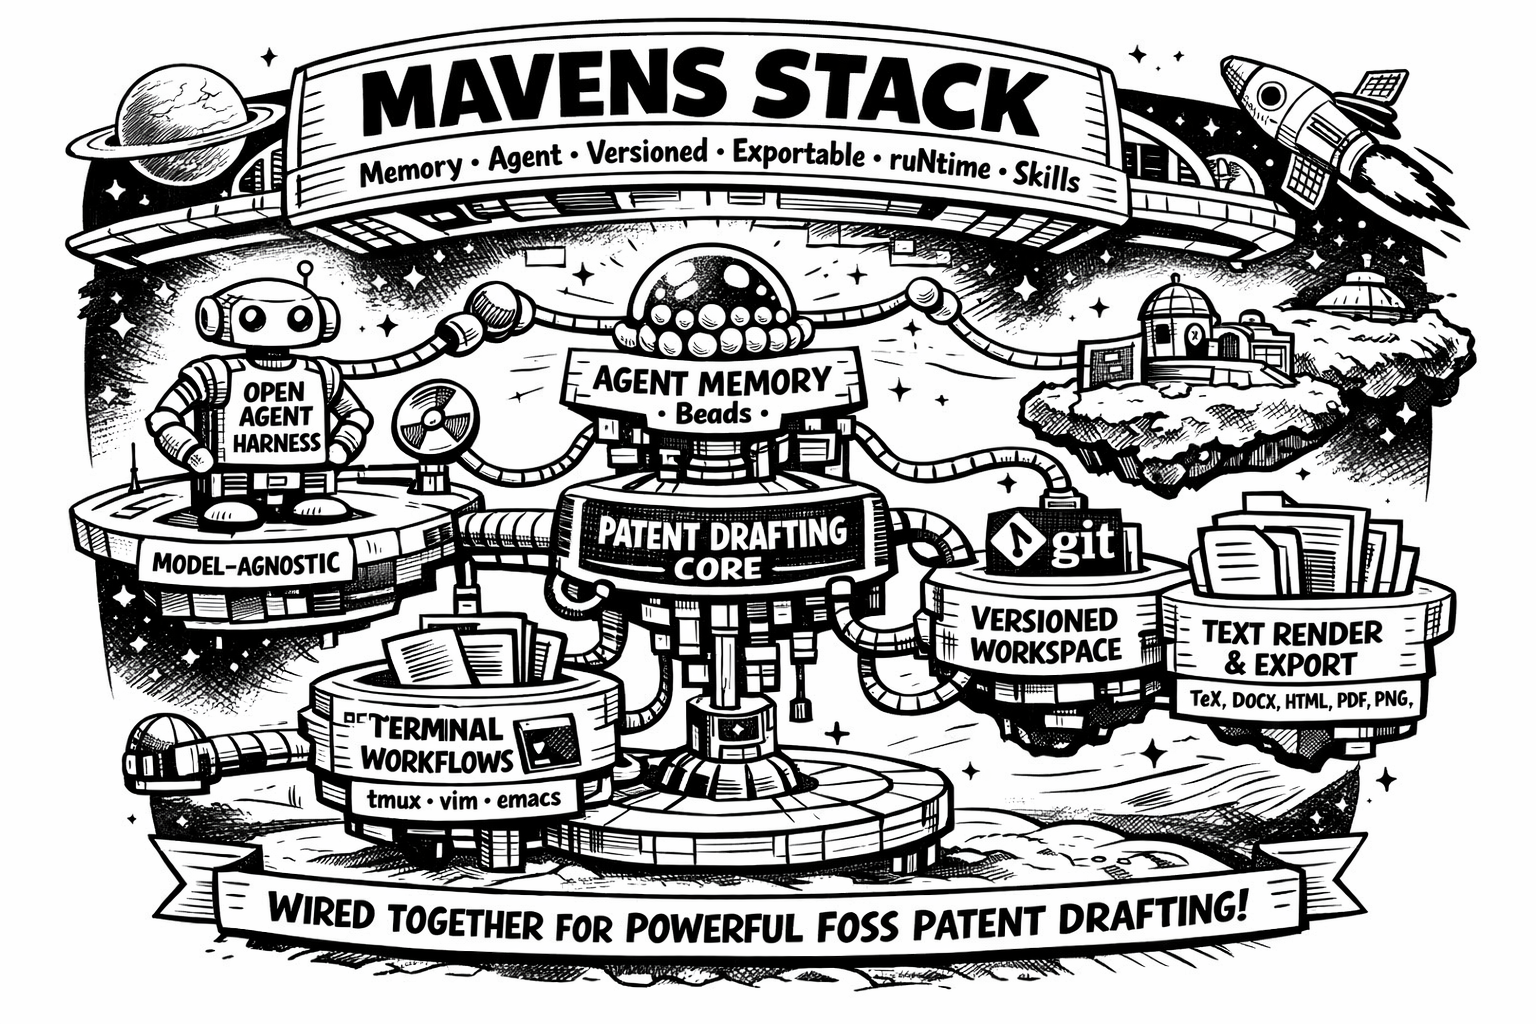
<p>Recent advances in free and open-source (FOSS) software distribution
have made it possible to build interesting things that would have been
significantly harder even a year ago, using a set of FOSS subcomponents
that are greater together than the sum of their respective parts:</p>
<ul>
<li>model-agnostic open agent harnesses (e.g., <a href="https://opencode.ai/">OpenCode</a>, <a href="https://shittycodingagent.ai/">pi</a>);</li>
<li>agent memory extensions (e.g., <a href="https://github.com/steveyegge/beads">beads</a>);</li>
<li>portable skill files and prompt assets (e.g., <a href="https://agentskills.io/home">agentskills</a>);</li>
<li>versioning and filesystem-backed workspace organization (e.g., Git)</li>
<li>intermediate text representations with rendering and export (e.g., TeX, docx, html, pdf, png, etc.);</li>
<li>terminal-native workflows (e.g., tmux, vim, emacs, etc.).</li>
</ul>
<p>Taken individually, these are just software methodologies/packages.
However, wired together, they transform into a powerful software
substrate for knowledge work that is unlike anything previously
available.<sup id="fnref:1"><a href="#fn:1" class="footnote-ref" role="doc-noteref">1</a></sup></p>
<p>As a shorthand, I&rsquo;m calling the pattern used to build this system the
<strong>MAVENS</strong> (<strong>M</strong>emory, <strong>A</strong>gent, <strong>V</strong>ersioned, <strong>E</strong>xportable,
ru<strong>N</strong>time, <strong>S</strong>kills) stack.<sup id="fnref:2"><a href="#fn:2" class="footnote-ref" role="doc-noteref">2</a></sup> The <strong>MAVENS</strong> stack is a new
paradigm in software development, and it represents a clear path to
unlocking value in knowledge work not only in patent practice, but
across many other domains.</p>
<blockquote>
<p>maven (noun): expert or person of skill; from Yiddish meyvn, from Hebrew mevin (מבין), “one who
understands.”</p>
</blockquote>
<figure class="blog-photo"><img src="/assets/img/ChatGPT%20Image%20Mar%2030,%202026,%2006_31_52%20PM.png" alt="TL;DR slop" title="TL;DR slop" loading="lazy" decoding="async" width="1200"><figcaption>TL;DR slop</figcaption></figure>

<p>One of the biggest wins of the <strong>MAVENS</strong> stack, and one that cannot be
emphasized enough, is that the FOSS constituent parts are
community-maintained, which allows the knowledge worker (e.g., patent practitioner)
to focus on <em>improving the things that matter to the knowledge worker</em> (the
runtime, skills and their outputs). The FOSS parts are essential, but
they are like the machinist&rsquo;s caliper or the electrician&rsquo;s
multimeter&ndash;generic tools that Just Work.</p>
<p>The next biggest win is that the open agent harness+memory can be used
separately to improve the <strong>MAVENS</strong> stack itself, leading to a
self-improvement feedback loop. For example, a client recently gave me a
bucket of TeX as a disclosure, including pages of formulas that would
have taken weeks to transcribe by hand, and which would have been
error-prone in any event. I was able to extend my <strong>MAVENS</strong> stack to
include a TeX-archive import feature, and map it onto the runtime.  This
code is completely reusable.</p>
<p>In another case, a colleague sent me a set of figures that did not have
reference numerals.  I quickly extended my <strong>MAVENS</strong> stack to add
them in programmatically based on the existing figure numbering and,
optionally, the content of an associated specification.  This was done
in minutes, and is a tool that can be used in perpetuity.  There are
many much more exotic examples of this type of work, all represented
using the <strong>MAVENS</strong> software architecture.</p>
<p>The step change here is not the ability to work with TeX from inventors
to preserve math fidelity, or do image generation/ processing, or any of
the other myriad things the software can do.  Those are just examples.
The leap in capabilities comes from the combination of the components,
that enable the <strong>MAVENS</strong> stack itself to be modified and improved,
while it is being used.</p>
<h2 id="confidentiality-and-privacy-and-governance-oh-my"><a class="heading-anchor" href="#confidentiality-and-privacy-and-governance-oh-my" aria-label="Link to this section: Confidentiality and Privacy and Governance, Oh my!">##</a>Confidentiality and Privacy and Governance, Oh my!</h2>
<p>A brief digression to discuss model access, where the devil is in the details.
For example, in the MS Azure model menagerie, there is an essential distinction
between models sold directly by Azure (&ldquo;Azure Direct models&rdquo;) and models that
are surfaced through Azure but are still from Partners and Community. The
former are the cleaner case: Microsoft hosts them in Microsoft&rsquo;s Azure
environment, under Microsoft&rsquo;s product and data-protection commitments, and
Microsoft says prompts and completions are not shared with other customers or
with the underlying model provider and are not used to train foundation models
absent permission or instruction.  Partner and Community models have their own ToS.</p>
<p>For example, whereas OpenAI models <em>are</em> Azure Direct, Anthropic&rsquo;s models
(Claude) are not, which means that the governing privacy posture is different, and
Anthropic&rsquo;s privacy policy and commercial terms are part of the analysis.
As such, before using the <strong>MAVENS</strong> stack, it is essential to
understand these terms in all of their excruciating detail.</p>
<p>Deployment characteristics also drive data location, and here the
official terms matter too. Azure speaks in terms of region, geography,
and DataZone. For Azure Direct models, data stored at rest remains in the
customer-designated Azure geography, but the location of processing for
prompts and responses depends on deployment type. A Standard or regional
deployment processes in the deployment region. A Global deployment may
process prompts and responses in any geography where the relevant model
is deployed. A DataZone deployment may process prompts and responses
anywhere within the Microsoft-defined data zone, today the United States
or the European Union. So if you stand up a US DataZone deployment,
processing may occur anywhere in the United States; if you stand one up
in an EU member state, processing may occur in that or another EU member
state. Thus, when using the <strong>MAVENS</strong> stack, it is essential to
become intimately familiar with model categories, deployment types,
geography of data at rest, and where inferencing may occur.</p>
<h2 id="deconstructing-the-mavens-stack"><a class="heading-anchor" href="#deconstructing-the-mavens-stack" aria-label="Link to this section: Deconstructing the MAVENS stack">##</a>Deconstructing the <strong>MAVENS</strong> stack</h2>
<p>I will now describe the technical underpinnings of the <strong>MAVENS</strong> stack
(in no particular order, and with AI slop images for maximum
engagement).</p>
<h2 id="1-the-agent-harness"><a class="heading-anchor" href="#1-the-agent-harness" aria-label="Link to this section: 1. the Agent harness">##</a>1. the <strong>A</strong>gent harness</h2>
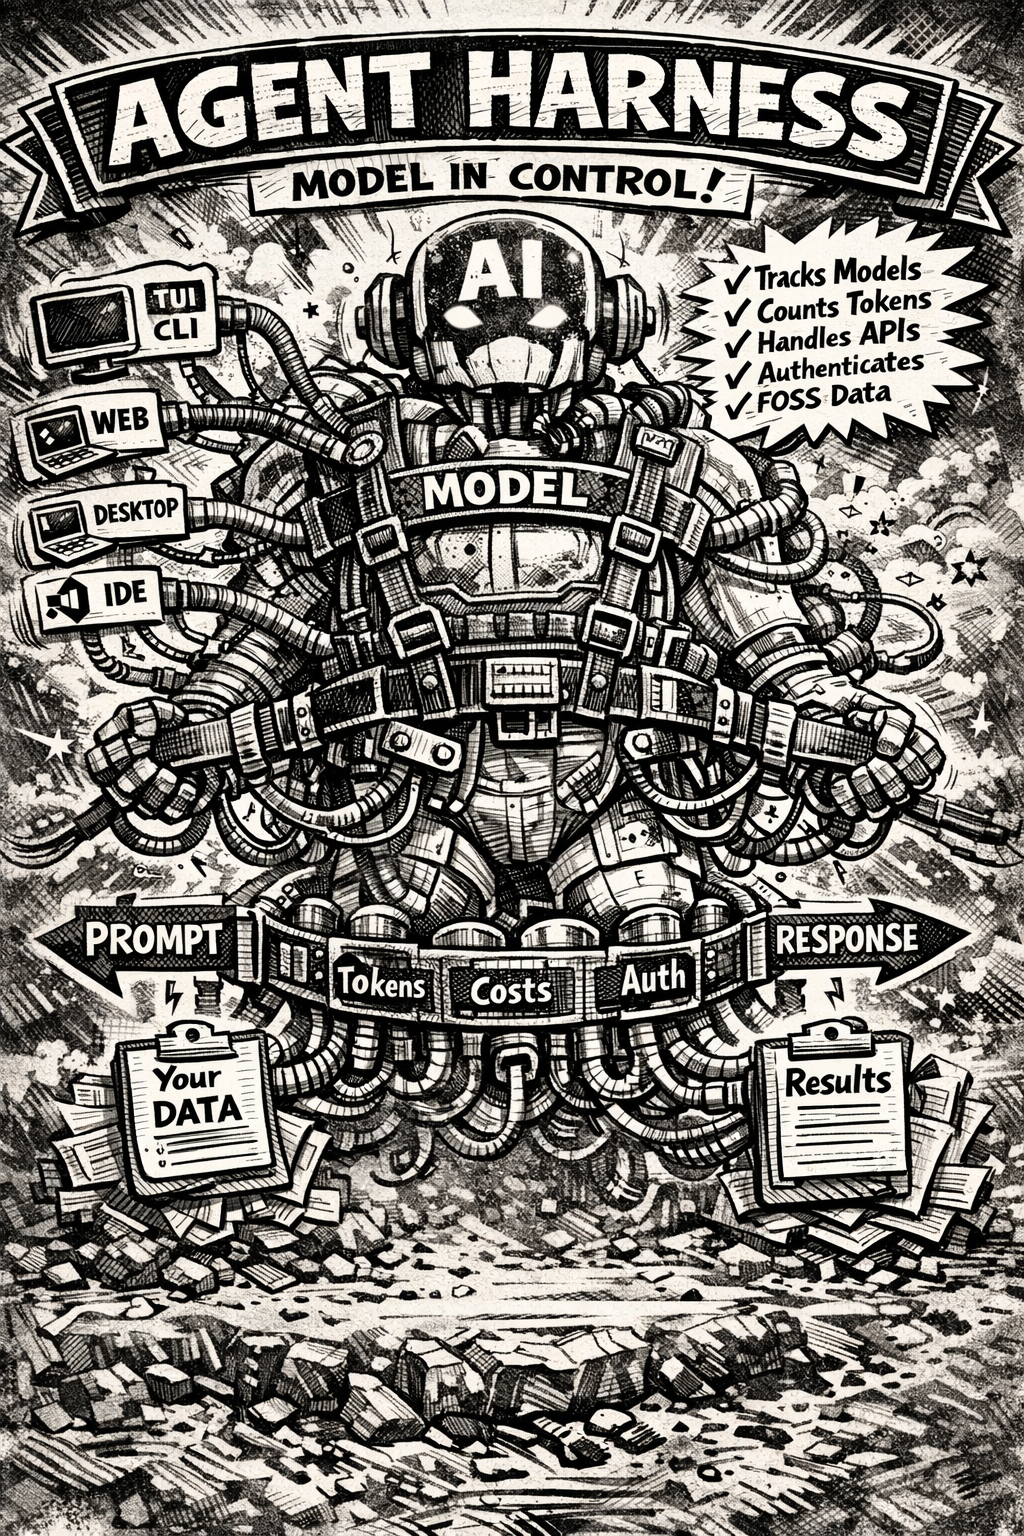
<p>An open agent harness allows the practitioner to interact with models in an
agentic way.  It&rsquo;s the practitioner&rsquo;s interface into the model provider(s)
(which can be any, including the latest and greatest from OpenAI,
Anthropic, Grok or others) and their respective model(s).  The agent
harness I&rsquo;m primarily using currently, OpenCode, can be accessed in a
Terminal User Interface (TUI, yay), CLI, via the web, desktop (beta,
pretty rough), and via an IDE like Visual Studio.</p>
<p>Thus, the <strong>MAVENS</strong> stack may require a change in <em>how</em> you work.  I will
argue this is for the better&ndash;programmers have known for a long time
that text, pipes and composability beat monolithic GUIs for software work,
hands down. And <strong>all knowledge work is now software work</strong>.</p>
<blockquote>
<p>This is the Unix philosophy: Write programs that do one thing and do
it well. Write programs to work together. Write programs to handle
text streams, because that is a universal interface.</p>
<p>&ndash; The Bell System Technical Journal. Bell Laboratories. M. D.
McIlroy, E. N. Pinson, and B. A. Tague. “Unix Time-Sharing System
Forward”. 1978. 57 (6, part 2). p. 1902</p>
</blockquote>
<p>Thus, it stands to reason that knowledge workers should embrace UNIX
principles for knowledge work, for maximum effectiveness.</p>
<figure class="blog-photo"><img src="/assets/img/harness%20ChatGPT%20Image%20Mar%2031,%202026,%2008_18_33%20PM.png" alt="Lovecraftian slop" title="Lovecraftian slop" loading="lazy" decoding="async" width="1200"><figcaption>Lovecraftian slop</figcaption></figure>

<h3 id="harness-engineering-and-harness-training"><a class="heading-anchor" href="#harness-engineering-and-harness-training" aria-label="Link to this section: Harness engineering and harness training">###</a>Harness engineering and harness training</h3>
<p>I already mentioned that coding agents can be used to improve the agent
harness and other aspects of the <strong>MAVENS</strong> stack, to extend
functionality on an as-needed basis, and that those
customizations/extensions compound over time.  Some recent
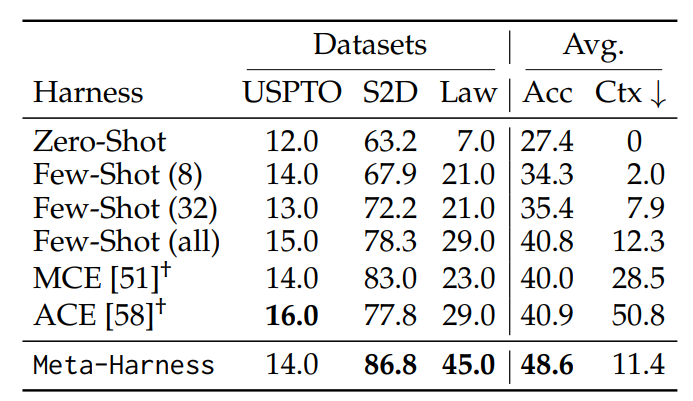
<a href="https://yoonholee.com/meta-harness/paper.pdf">research</a> in
this area hints at what will be coming down the pike soon:</p>
<blockquote>
<p>Changing the harness around a fixed large language model (LLM) can
produce a 6× performance gap on the same benchmark [46]. The
<em>harness</em>&ndash;the code that determines what to store, retrieve, and show
to the model&ndash;often matters as much as the model itself.</p>
</blockquote>
<p>This paper showed automated harness engineering produces better
classifications, faster, in legal and legal adjacent domains &ndash;
including USPTO molecule-reactant datasets and criminal charging from
case descriptions &ndash; than hand-curated techniques.  Meta-Harness
significantly outperformed
<a href="https://aclanthology.org/2024.emnlp-main.452.pdf">LawBench</a>, using far
fewer tokens.</p>
<figure class="blog-photo"><img src="/assets/img/2026-03-30%2022_17_14-dev.or..._blog_2.png" alt="Meta-Harness" title="Meta-Harness" loading="lazy" decoding="async" width="1200"><figcaption>Meta-Harness</figcaption></figure>

<p>This was accomplished via harness training:</p>
<blockquote>
<p>At a high level, [Meta-Harness] repeatedly proposes, evaluates, and
logs new harnesses.
[&hellip;]
[B]y leaving diagnosis and edit decisions to the proposer rather than
hard-coding search heuristics, Meta-Harness can improve automatically
as coding agents become more capable.</p>
</blockquote>
<p>For now, I&rsquo;m left to wonder, what would it take for a patent
practitioner, or another knowledge worker, to learn to trust a
self-improving orchestration layer?  More on this in a future post,
perhaps.<sup id="fnref:3"><a href="#fn:3" class="footnote-ref" role="doc-noteref">3</a></sup></p>
<h3 id="clawed-open"><a class="heading-anchor" href="#clawed-open" aria-label="Link to this section: Clawed Open">###</a>Clawed Open</h3>
<p>While I was doing final edits on this post, as if on cue, the interwebs
began to vibrate with the news that the source code for the Claude Code
harness had escaped into the wild.</p>
<p>The code was quickly <a href="https://github.com/instructkr/claw-code">ported</a>
via purported clean room engineering.  The claw-code developer wrote the
following:</p>
<blockquote>
<p>At 4 AM on March 31, 2026, I woke up to my phone blowing up with
notifications. The Claude Code source had been exposed, and the entire
dev community was in a frenzy. My girlfriend in Korea was genuinely
worried I might face legal action from Anthropic just for having the
code on my machine — so I did what any engineer would do under
pressure: I sat down, ported the core features to Python from scratch,
and pushed it before the sun came up.</p>
<p>The whole thing was orchestrated end-to-end using oh-my-codex (OmX) by
@bellman_ych — a workflow layer built on top of OpenAI&rsquo;s Codex
(@OpenAIDevs). I used $team mode for parallel code review and $ralph
mode for persistent execution loops with architect-level verification.
The entire porting session — from reading the original harness
structure to producing a working Python tree with tests — was driven
through OmX orchestration.</p>
<p>The result is a clean-room Python rewrite that captures the
architectural patterns of Claude Code&rsquo;s agent harness without copying
any proprietary source. I&rsquo;m now actively collaborating with
@bellman_ych — the creator of OmX himself — to push this further. The
basic Python foundation is already in place and functional, but we&rsquo;re
just getting started. Stay tuned — a much more capable version is on
the way.</p>
</blockquote>
<p>Without taking a position as to the legitimacy of this activity, a few things seem clear.</p>
<p>First, Anthropic needs better InfoSec.  They seem to have physical
security buttoned up:</p>
<blockquote>
<p>Even this blankness is doled out grudgingly: all but two of the ten
floors that the company occupies are off limits to outsiders. Access
to the dark heart of the models is limited even further. Any unwitting
move across the wrong transom, I quickly discovered, is instantly
neutralized by sentinels in black. When I first visited, this past
May, I was whisked to the tenth floor, where an airy,
Scandinavian-style café is technically outside the cordon sanitaire.
Even there, I was chaperoned to the bathroom.
&ndash; <a href="https://www.newyorker.com/magazine/2026/02/16/what-is-claude-anthropic-doesnt-know-either">https://www.newyorker.com/magazine/2026/02/16/what-is-claude-anthropic-doesnt-know-either</a></p>
</blockquote>
<p>Second, the claw-code repository is of a piece with the types of
LLM-based copying risks people have warned about for a while now in the
IP community, which I <a href="https://blog.tilton.co/2026/02/26/the-patent-programmer-practitioner-lift-hills-and-drops-on-the-ai-forevercoaster.html#jetpacks-baby">wrote about</a> in reference to (somewhat ironically) the Anthropic C compiler project,
and which have, in the interim, cropped up in <a href="https://malus.sh/">other contexts</a>.</p>
<p>Third, setting aside the morality of the Claude clones, for practical
purposes, the horse is out of the barn, and the digital commons will be
the immediate beneficiary.  Everyone can now read the Claude Harness,
its code and its prompts to develop their own coding agents.  They can
do so in conjunction with <em>any models</em>.  This leak seems likely to
include trade secret information that, until yesterday, appeared to
have given Claude Code a non-insignificant edge over competitors
like OpenAI Codex.<sup id="fnref:4"><a href="#fn:4" class="footnote-ref" role="doc-noteref">4</a></sup></p>
<p>Having said that, some of the technical details about the inner workings
of Claude Code sound kind of obvious in hindsight.  A more tinfoil-hat
interpretation is that Anthropic may not be terribly unhappy to have the
wider FOSS world iterate on parts of the harness. But that is
speculation.</p>
<h3 id="porcelain-not-plumbing"><a class="heading-anchor" href="#porcelain-not-plumbing" aria-label="Link to this section: Porcelain, not plumbing">###</a>Porcelain, not plumbing</h3>
<p>One of the practical upsides of using an agent harness is that it
abstracts away all of the LLM drudgery (counting tokens, counting
costs, authenticating with providers, keeping a current list of models
and their respective capabilities/parameters, etc.). Anyone who has spent any
time coding against an LLM knows this bean counting starts to feel like medieval
torture after a while, especially due to constant drift and churn
among providers and their model offerings.  The harness can simply ingest data
from a FOSS API (e.g., <a href="https://models.dev/">models.dev</a>) that the community
keeps up to date.  On its own, this is a huge win. All of the API
programming, which can change in
<a href="https://azure.microsoft.com/en-us/updates?id=retirement-azure-ai-document-intelligence-v20-api-will-be-retired-on-31-august-2026">sudden</a>
and <a href="https://developers.openai.com/api/docs/guides/migrate-to-responses">highly disruptive</a> ways,
is a thing of the past. A lot of boilerplate programming is no longer
necessitated, given the better abstractions of the <strong>MAVENS</strong> stack.</p>
<p>Open agent harnesses also have a flexible model layer. A useful
knowledge work system should be able to work with whichever models make
sense in the moment: local models where they are good enough or
operationally attractive, frontier hosted systems where stronger
performance is worth it. Ad hoc or case-by-case selection should be
available when it&rsquo;s called for or as input modalities dictate.  It&rsquo;s
nice to be able to ask OpenAI and Anthropic the same question,
back-to-back, and compare responses.<sup id="fnref:5"><a href="#fn:5" class="footnote-ref" role="doc-noteref">5</a></sup></p>
<p>One potential wrinkle in the <strong>MAVENS</strong> stack is lackluster web and desktop
support.  While usable, they are not as polished.  But if you&rsquo;ve read
this far, there&rsquo;s a good chance a terminal interface not only might not
scare you, but could be just the thing you&rsquo;re looking for.</p>
<h2 id="2-agent-memory"><a class="heading-anchor" href="#2-agent-memory" aria-label="Link to this section: 2. agent Memory">##</a>2. agent <strong>M</strong>emory</h2>
<h3 id="screaming-at-goldfish"><a class="heading-anchor" href="#screaming-at-goldfish" aria-label="Link to this section: Screaming at goldfish">###</a>Screaming at goldfish</h3>
<p>An <a href="https://steve-yegge.medium.com/introducing-beads-a-coding-agent-memory-system-637d7d92514a">excerpt</a>
from Steve Yegge that might resonate with you if you&rsquo;ve tried using an
agentic model to do anything remotely complex without agent memory (vibe
coding, coding with a straight face, or otherwise):</p>
<blockquote>
<p>Your agent enthusiastically begins working on phase 1 (out of 6). You go
through the whole canonical multi-step vibe coding workflow loop
together: design the solution, review the design, write code, review
code, make fixes, write more tests, review, cleanup, rebase, update
plans, git operations. (All stuff in our book!)</p>
<p>So far, the agent is happy, and you are happy. Everyone is so, so happy.</p>
<p>The agent eventually finishes phases 1 and 2 (out of 6), with you
repeating this dev loop many times.</p>
<p>It’s working, but during this time, several compactions/restarts happen,
which resets the agent’s memory.</p>
<p>By the start of phase 3 (out of 6), the AI has mostly forgotten where it
came from. It wakes up, plops in your video cassette, and reads about
phase 3. It then declares, “Oh wow, this is a big project, I’m going to
break it into five phases and create a markdown plan.” Which should
sound eerily familiar.</p>
<p>Then it begins working on phase 1 (out of 5) of phase 3 (out of 6).
Except it just calls it “phase 1”, with no mention of the six outer
phases it was just working on.</p>
<p>You start to sweat.</p>
<p>The agent finishes the first two phases 1 and 2 (out of 5), which takes
many more compactions, and it has been displaying signs of increasing
dementia along the way.</p>
<p>When the agent arrives at phase 3 (out of 5) of phase 3 (out of 6), it
has gone full-blown bugshit amnesiac, and it announces triumphantly:</p>
<p>“Congratulations, the system is DONE! 🎉 Let’s start manual testing! 🚀”</p>
<p>And you’re like, “Woah… w-what? What… about… all the other phases? The
inner ones and outer ones? I distinctly remember a lot more phases!”</p>
<p>And they deadass look you in the eye and say, “What phases?”</p>
<p>And you bite back a scream, and go look in their markdown plan, only to
discover in horror that they have been creating a dozen 6-phase plans a
day for the past three weeks since your last Great Markdown Purge, and
you have literally hundreds of new markdown files, all with low-context
titles like cleanup-tech-debt-plan-phase-4.md — all partly implemented,
all partly obsolete, all 100% useless.</p>
<p>C’mon, raise your hand if this has happened to you. ✋ If you’re not
sure, you might want to go look in your plans/ directory. Surprise! 🎉</p>
<p>After six months of this situation happening like twenty times a day, if
you’re at all like me, you start thinking, I need a Plan Manager.</p>
</blockquote>
<p>If you&rsquo;ve tried using markdown-based plan files to guide an agent,
you&rsquo;ve probably choked back that same sweaty sob/scream, and you might
know that agent memory is the way out.</p>
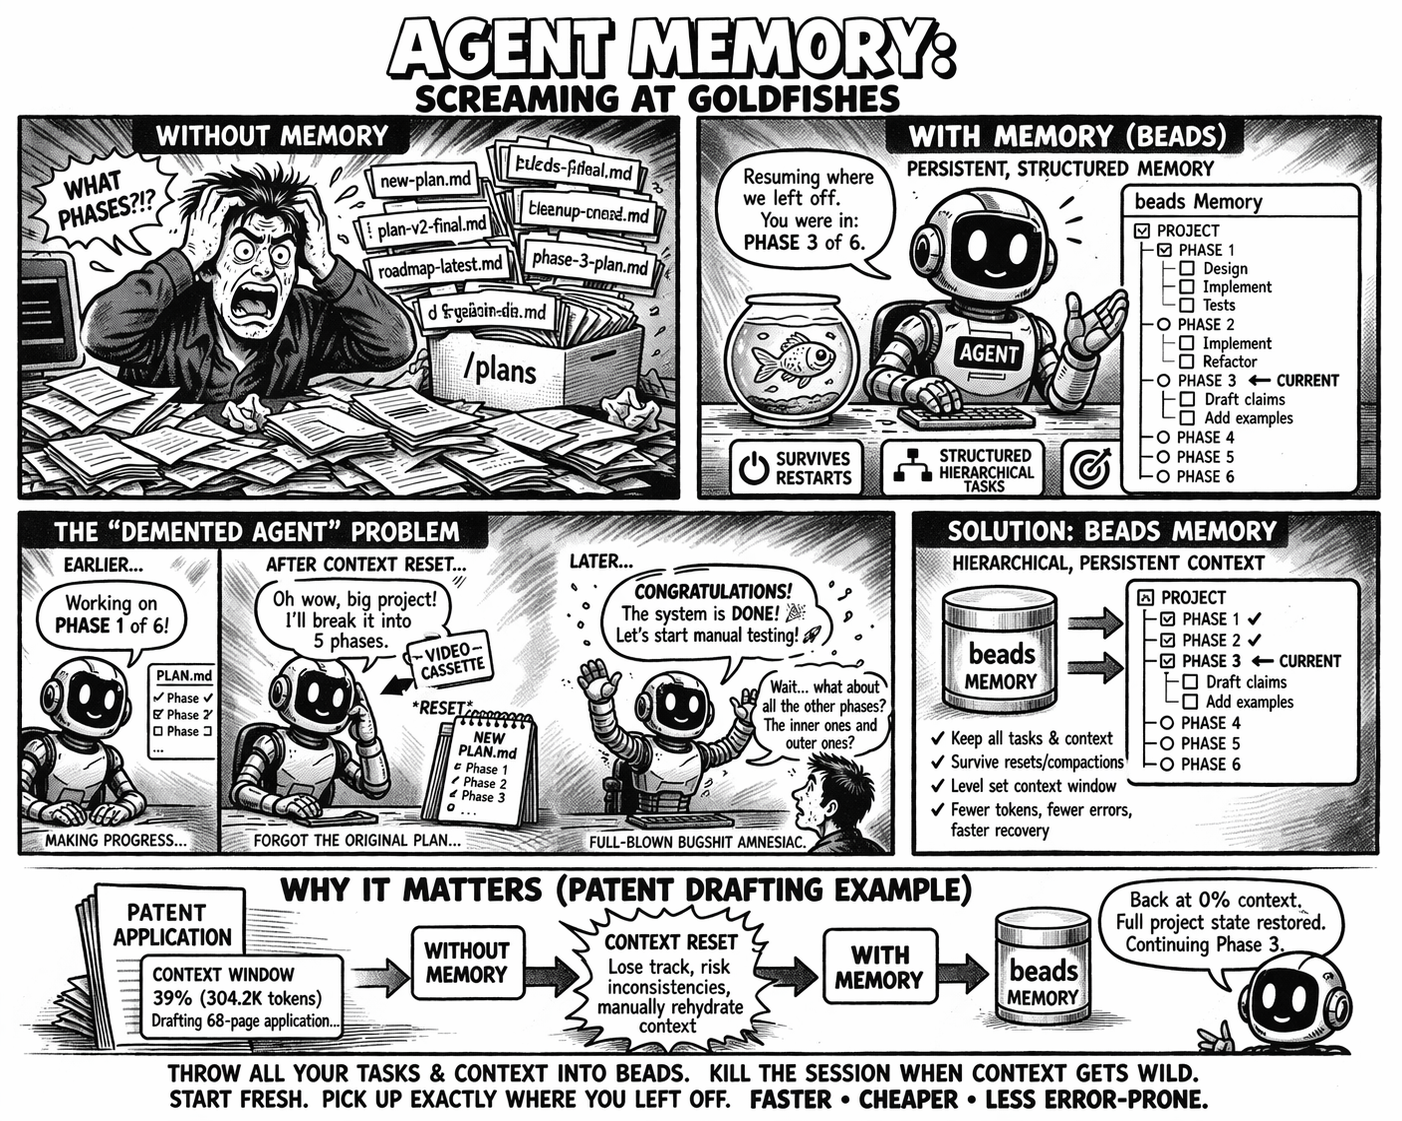
<p>A tool like beads helps to alleviate the &ldquo;demented agent&rdquo; issue by
giving the model &ldquo;a persistent, structured memory&rdquo; that it can use &ldquo;to
handle long-horizon tasks without losing context&rdquo;.<sup id="fnref:6"><a href="#fn:6" class="footnote-ref" role="doc-noteref">6</a></sup></p>
<p>However, for patent practitioners, the approximate parallel is a model
context resetting/compacting, while in the midst of drafting a 68-page
patent application, with a context window at 39% (304.2K tokens).
Regardless of the knowledge domain, the ability to level set the context
window predictably and somewhat losslessly becomes Very Important.</p>
<figure class="blog-photo"><img src="/assets/img/memory%20ChatGPT%20Image%20Mar%2031,%202026,%2008_25_47%20PM.png" alt="no more goldfishes" title="no more goldfishes" loading="lazy" decoding="async" width="1200"><figcaption>no more goldfishes</figcaption></figure>

<p>Previously, you&rsquo;d need to attempt to store all of the things that the
agent needs to know in flat text files and find a way to
reinject that context.  With memory, you can just throw all
of your implementation tasks and context into hierarchical issues à la
beads, and kill the model session and start a fresh one if the context
gets too wild and woolly.  When you come back, at 0% context window
consumed, the model still has (mostly) everything it needs to pick up
where it left off.  This is simultaneously a faster, cheaper and less
error-prone way to use agents.<sup id="fnref:7"><a href="#fn:7" class="footnote-ref" role="doc-noteref">7</a></sup></p>
<h3 id="editing-modalities---agents-and-subagents"><a class="heading-anchor" href="#editing-modalities---agents-and-subagents" aria-label="Link to this section: Editing modalities - Agents and Subagents">###</a>Editing modalities - Agents and Subagents</h3>
<p>Some agent harnesses have the ability to use editing modalities, or
agent modes.  Interestingly, Pi does not expose separate modes in quite the same way.  OpenCode ships with two: Plan and Build,
which, respectively, (essentially) provide read-only and write access to the
filesystem including use of tools.  A typical patent drafting workflow
looks like this:</p>
<ul>
<li>Plan complex features/functionality, optionally based on existing
language in plan mode. This is all done in memory with iterative model
turns.</li>
<li>Once the plan looks good, save it as persistent hierarchical tasks using beads.</li>
<li>Switch to build mode and begin iteratively carrying out the plan.
This involves generating new files or editing existing ones.</li>
</ul>
<p>OpenCode ships with two sub-agents: General and Explore, which
respectively, can research complex questions and execute multi-step
tasks (including with tools); and quickly search files (think Grep, with
extras).</p>
<p>The agent/subagent layer is where the <strong>MAVENS</strong> stack starts to feel
like a real knowledge work environment. In OrdinarySkill.ai, I modify the
default agent set with additional agents and subagents that are
purpose-built to do patent-specific tasks.  It works amazingly well&ndash;if
you have used a coding agent, it&rsquo;s like that&ndash;but for patent work.</p>
<p>The OpenCode API <a href="https://opencode.ai/docs/agents/">documentation</a> is a
good read if you are interested in more details about OpenCode&rsquo;s
agent implementation.</p>
<h2 id="3-versioning"><a class="heading-anchor" href="#3-versioning" aria-label="Link to this section: 3. Versioning">##</a>3. <strong>V</strong>ersioning</h2>
<p>Git is old hat for most software developers, and software patent
practitioners.  Suffice it to say that keeping the artifacts of patent
drafting in a distributed VCS is very comforting, for all of the reasons
it is in software development.</p>
<h2 id="4-export"><a class="heading-anchor" href="#4-export" aria-label="Link to this section: 4. Export">##</a>4. <strong>E</strong>xport</h2>
<p>Everything up to this point has been a reversion to the text-first,
composable Unix mode: a terminal, a good editor, plain text files, and
version control are a very natural environment for agentic work. It&rsquo;s a
shame that reality must intrude, in the form of document production.</p>
<p>For patent work, Word is the <em>lingua franca</em>.  The USPTO effectively
<a href="https://www.uspto.gov/subscription-center/2024/uspto-notice-clarifying-requirement-non-docx-surcharge">penalizes</a>
applicants for filing PDFs, which is only a slightly nuttier decision
than the one to standardize the entire filing system around the dumpster
fire of a file format that is docx.</p>
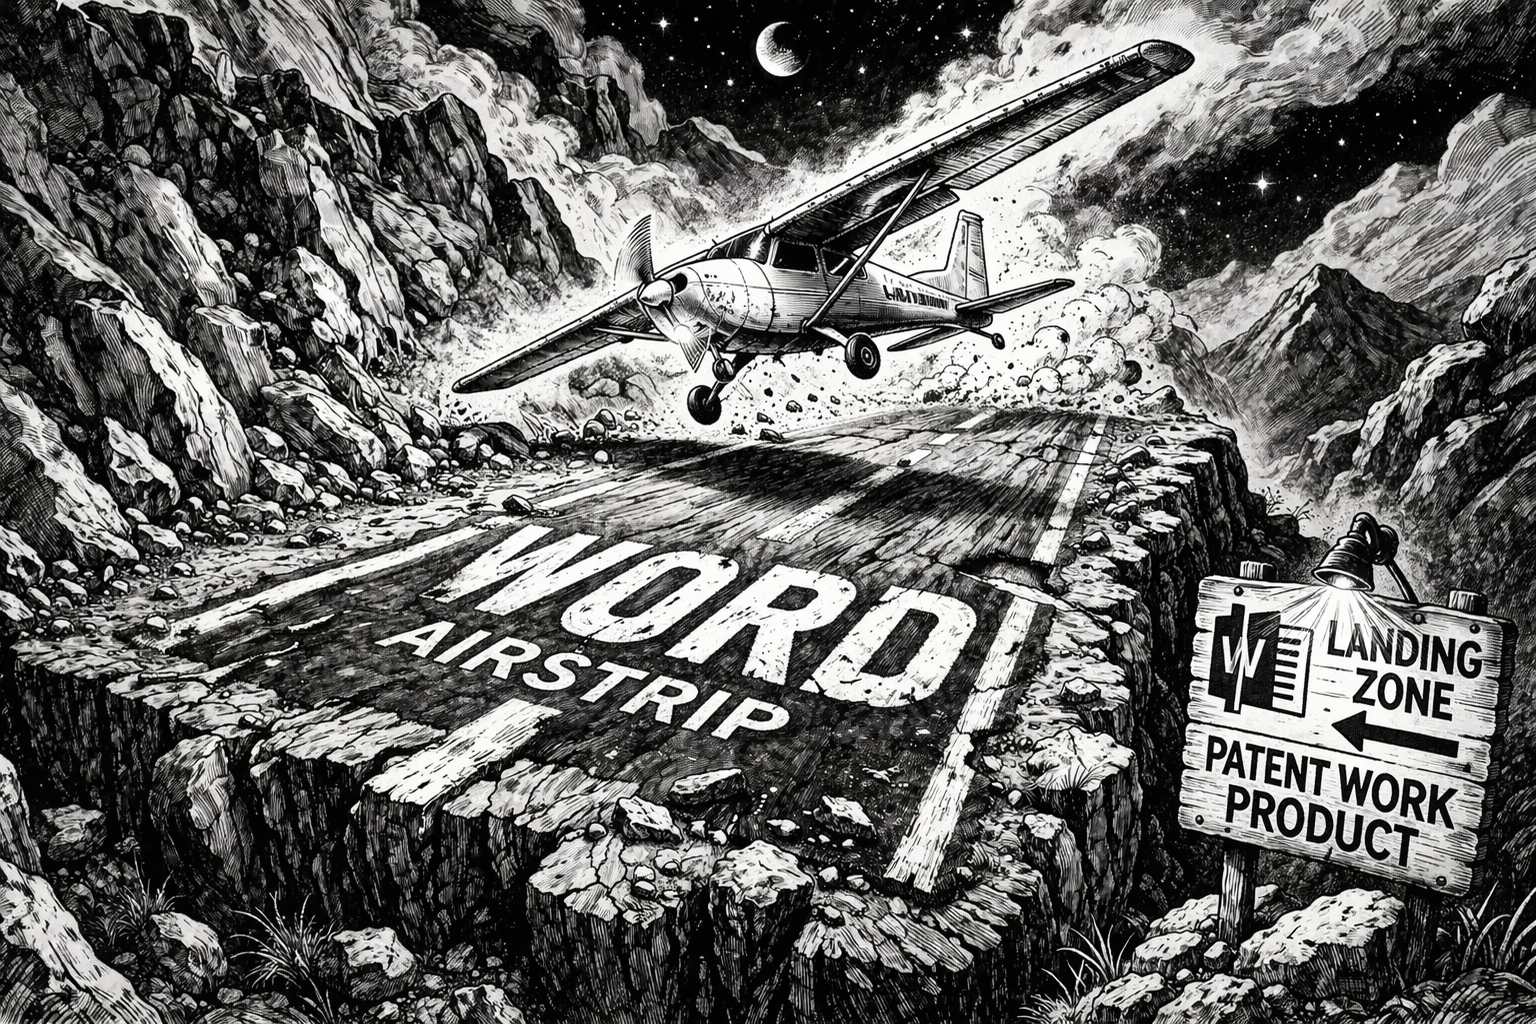
<p>Regardless, Word is the craggy remote airstrip where 99% of patent
deliverables must land.</p>
<figure class="blog-photo"><img src="/assets/img/ChatGPT%20Image%20Mar%2030,%202026,%2009_06_00%20PM.png" alt="WRD" title="WRD" loading="lazy" decoding="async" width="1200"><figcaption>WRD</figcaption></figure>

<p>That means the drafting environment must be able to move cleanly from
structured source into picture-perfect MS Word output. TeX, Pandoc, and
related tooling are not glamorous, but they are powerful building blocks
for getting there.</p>
<p>However, as much as I enjoy dumping on Word, Microsoft has in recent
years done some things that make working on Windows not only bearable
but so interoperable with Unix that there&rsquo;s almost zero friction.  I
have nothing but love for Windows Subsystem for Linux, which allows any
<strong>MAVENS</strong> stack to directly interoperate with Word and the Microsoft
filesystem.  The fact that WSL has Arch Linux out of the box is the cherry
on top.</p>
<h2 id="5-the-runtime"><a class="heading-anchor" href="#5-the-runtime" aria-label="Link to this section: 5. The ruNtime">##</a>5. The ru<strong>N</strong>time</h2>
<p>The runtime includes matter state that the system can reason about.<br>
Patent drafting is not just &ldquo;write a lot of text.&rdquo;  It is a constrained
document-building problem with dependencies everywhere: claims and
specification must stay aligned, figures need to map cleanly into the
detailed description, optional sections come and go, and terminology has
to remain coherent over tens of pages.  The ruNtime provides a stable
substrate for this work that is grounded in document structure and
practitioner know-how.</p>
<p>The runtime is where I think a lot of the durable value sits in the
<strong>MAVENS stack</strong>, for patent practitioners but really for all knowledge
workers who apply it.  Agent harnesses will improve, models will churn,
and export tooling will remain mildly cursed. A well-designed runtime
gives all of those moving parts a common contract.  It lets different
agents, skills, and renderers operate against the same data without
each inventing its own private version of reality. For me, this is the
real promise: less hidden state, fewer surprises, and a workflow that
gets better because the software actually knows what the work is.</p>
<h2 id="6-the-skills"><a class="heading-anchor" href="#6-the-skills" aria-label="Link to this section: 6. The Skills">##</a>6. The <strong>S</strong>kills</h2>
<p>If the runtime is the source of truth, the skills are the reusable
recipes/moves.<br>
A skill is not just a giant prompt pasted into a text file. It is a
named, portable procedure for doing a recurring piece of patent work:
routing a workflow, drafting a first pass of particular text, reviewing
for consistency, harmonizing terminology, generating a figure prompt,
flagging possible support issues, and otherwise teeing up issues for
practitioner review. The important thing is that skills can be recursively
improved independently of the agent harness or model provider, with the
practitioner as a guide.  Skills are packages of reusable technique.</p>
<p>Once a useful drafting pass or review sequence exists, it can be reused
across matters, sharpened over time, and composed with other skills,
without collapsing into prompt soup.  Instead of evaporating with
individual chats, this knowledge starts compounding in an organized
repository.  And these tools are editable, <em>in the tool</em>.  So after you
finish a session where you correct a bunch of things, you can say
something like &ldquo;<em>update my claims review skill file to include avoiding
passive voice and nominalizations</em>.&rdquo;  It will do it and report
back.  This is an incredibly powerful, and fast, way to work, where the
practitioner can crystallize and preserve judgment for repeated use.</p>
<p>This is also one of the more interesting places for professional
differentiation.  While the <strong>MAVENS</strong> stack is open, the best skills
can still reflect a practitioner&rsquo;s own drafting habits, review
heuristics, and sense of what makes an application good.  Good taste is
difficult to express in code, but the skill layer moves us closer.</p>
<h2 id="closing"><a class="heading-anchor" href="#closing" aria-label="Link to this section: Closing">##</a>Closing</h2>
<p>AI software tooling has become critical to patent practice. It is not
docketing software, accounting software, or some other ancillary system,
removed from the legal work. An AI patent drafting stack reaches
directly into the substantive legal function itself. It does not
displace ultimate practitioner responsibility for what is claimed, argued,
supported and filed.  But it sits close enough to the heart of the work
that it must be treated with the same seriousness.</p>
<p>At the same time, there is a <a href="https://blog.tilton.co/2026/02/26/the-patent-programmer-practitioner-lift-hills-and-drops-on-the-ai-forevercoaster.html">merger</a>
underway between software functions and legal functions, which implies a
<strong>merger of tooling</strong>. As legal work itself becomes more
software-shaped, the tools built for sophisticated software work become
increasingly applicable to sophisticated legal work.</p>
<p>What has become possible only very recently is the ability to assemble
drafting environments from mature FOSS tooling, and to use them to
access the best models available, while fully customizing the system for
a given knowledge work domain, allowing the knowledge worker to build or
shape a workflow around the actual work. For patent practice in
particular, drafting has enough structure, repeatability, and
document-centric gravity that this kind of environment can be very
effective.</p>
<p>As I use agentic systems more, and particularly the <strong>MAVENS</strong> stack, I
find myself running dozens of lightweight agents interactively to solve
different problems concurrently.  tmux allows me to run these agent
sessions persistently, and no file, directory or data source is safe
from the grip of my <strong>MAVENS</strong> stack.  One agent tees up a first pass
critique of a claim set, while another steps through an office action
analysis workflow, another generates terrible images for a draft blog post.
This is the promise of agentic AI&ndash;on-demand, parallel application of
knowledge models to digital artifacts, wherever they may be.</p>
<p>In any event, I hope that you, too, <a href="https://mitchellh.com/writing/my-ai-adoption-journey">always have an agent running</a>.</p>
<h2 id="notes"><a class="heading-anchor" href="#notes" aria-label="Link to this section: Notes">##</a>Notes</h2>
<div class="footnotes" role="doc-endnotes">
<hr>
<ol>
<li id="fn:1">
<p>There are, naturally, optional components that can be added
to make the stack operator surface more appealing (e.g., nvim, tmux,
WSL, etc.), or to support different workflows (e.g., web views,
desktop extensions), but those are the main components.&#160;<a href="#fnref:1" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:2">
<p>When it comes to gratuitous acronyms, <a href="https://cloud.google.com/mysql/lamp">why should software
developers have all the fun?</a>.&#160;<a href="#fnref:2" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:3">
<p>There are other projects that might have interesting
applications in this area, including self-correcting or
self-learning approaches inspired by <a href="https://github.com/karpathy/autoresearch">auto
research</a>.  These
approaches can be <a href="https://www.tbench.ai/">quantified</a>.&#160;<a href="#fnref:3" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:4">
<p>There are also even less scrupulous uses this code leak
could be put to.&#160;<a href="#fnref:4" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:5">
<p>FOSS agent harnesses also confer all of the other attendant
benefits found in most FOSS software, like auditability, stability,
large user base making bugs shallow, etc.&#160;<a href="#fnref:5" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:6">
<p><a href="https://github.com/steveyegge/beads">https://github.com/steveyegge/beads</a>&#160;<a href="#fnref:6" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
<li id="fn:7">
<p>Beads isn&rsquo;t the only way to approach agent memory.  For
example, Claude recently rolled out a
<a href="https://code.claude.com/docs/en/memory">form</a> of memory that&rsquo;s less
explicit and non-external like beads.  Others may emerge. The great
thing about the <strong>MAVENS</strong> framework is that swapping out the Memory
component from beads to something else can be done in a few minutes,
if new libraries come along.&#160;<a href="#fnref:7" class="footnote-backref" role="doc-backlink">&#x21a9;&#xfe0e;</a></p>
</li>
</ol>
</div>
]]></content><author><name>Noah K. Tilton</name></author><category term="patents"/><category term="ai"/><category term="software"/><category term="open-source"/><category term="drafting"/><category term="knowledge-work"/><category term="mavens-stack"/><summary type="html">##Introducing the MAVENS Stack Recent advances in free and open-source (FOSS) software distribution have made it possible to build interesting things that would have been significantly harder even a year ago, using a set of FOSS subcomponents that are greater together than the sum of their respective parts:
model-agnostic open agent harnesses (e.g., OpenCode, pi); agent memory extensions (e.g., beads); portable skill files and prompt assets (e.g., agentskills); versioning and filesystem-backed workspace organization (e.g., Git) intermediate text representations with rendering and export (e.g., TeX, docx, html, pdf, png, etc.); terminal-native workflows (e.g., tmux, vim, emacs, etc.). Taken individually, these are just software methodologies/packages. However, wired together, they transform into a powerful software substrate for knowledge work that is unlike anything previously available.1</summary></entry><entry><title type="html">The Patent Programmer-Practitioner: Lift Hills and Drops on the AI Forevercoaster</title><link href="https://blog.tilton.co/2026/02/26/the-patent-programmer-practitioner-lift-hills-and-drops-on-the-ai-forevercoaster.html" rel="alternate" type="text/html" title="The Patent Programmer-Practitioner: Lift Hills and Drops on the AI Forevercoaster"/><published>2026-02-26T00:00:00-06:00</published><updated>2026-07-24T10:55:39-05:00</updated><id>https://blog.tilton.co/2026/02/26/the-patent-programmer-practitioner-lift-hills-and-drops-on-the-ai-forevercoaster</id><content type="html" xml:base="https://blog.tilton.co/2026/02/26/the-patent-programmer-practitioner-lift-hills-and-drops-on-the-ai-forevercoaster.html"><![CDATA[<p><em>This is a longish, and long-overdue post with some of my thoughts (aka
lightly edited brain dump/screed) on developing and using agentic AI for
patent practice.</em></p>
<h2 id="how-it-started"><a class="heading-anchor" href="#how-it-started" aria-label="Link to this section: How it Started">##</a>How it Started</h2>
<div class="highlight"><pre tabindex="0" style="color:#e6edf3;background-color:#0d1117;-moz-tab-size:4;-o-tab-size:4;tab-size:4;-webkit-text-size-adjust:none;"><code class="language-text" data-lang="text"><span style="display:flex;"><span>commit 59014c091efa219987779af1c0844c4aa0304ee0
</span></span><span style="display:flex;"><span>Author: Noah K. Tilton &lt;code@tilton.co&gt;
</span></span><span style="display:flex;"><span>Date:   Sun Jan 7 17:00:08 2024 -0600
</span></span><span style="display:flex;"><span>
</span></span><span style="display:flex;"><span>    blah
</span></span></code></pre></div><p>I made this initial commit on a Sunday afternoon with a listless
message I use when I&rsquo;m too lazy or tired to type a descriptive one.
This is not usually a problem, because most of the software I write is
not intended to be read or used by others.  I have not worked as a
professional software developer for over a decade, and as a patent
prosecution partner with a robust practice, I still do not.</p>
<p>However, in late 2023, something changed that, looking back, was a
momentous time in my journey as a patent practitioner.  Over the
holidays, a colleague repeatedly pestered me (in a good way) about
ChatGPT, and specifically, whether it could be used in the practice of
patent law.</p>
<p>In the nine months or so leading up to that time, during the initial
GPT-3 era, I was like a lot of other people in the IP space &ndash; ambiently
familiar with large language model (LLM) technology, but focused on
other things.  I had also developed a bit of trepidation toward LLMs,
due to an uneasiness I had felt during early experimentation with GPT,
that I was riding up a lift hill, and once I reached the crest and
started the first precipitous drop, there would be no getting off.  This
is still the best metaphor I can conjure for the viral, exponential
arrival of LLMs &ndash; as a rollercoaster ride that never ends.</p>
<figure class="blog-photo"><img src="/assets/img/tron.gif" alt="Tron" title="Tron" loading="lazy" decoding="async" width="1200"><figcaption>Tron</figcaption></figure>

<p>I had some downtime over the holidays, and I usually code during that
period since it&rsquo;s cold, dark and I can&rsquo;t sit still.  Within a few weeks of
being nagged by that persistent colleague, I had a working web app,
later renamed OrdinarySkill.ai (OS), that performed a variety of
automated LLM-based drafting and prosecution tasks.  While I made OS
available for use to others, I had no aspirations to be a software CEO.
Any usefulness to others was purely incidental.  Notwithstanding, over
1B tokens have been consumed by users of OS to date, for a variety of
things.</p>
<p>In sum, OS was an early indicator of the disruptive potential that LLMs
would have on the practice of patent law, and it was soon surpassed by
more capable (read: more user-friendly) tooling.  I continued working on it
actively until Fall of 2025, and it dramatically accelerated aspects of my
practice, which did not go unnoticed.</p>
<h2 id="buy-or-build"><a class="heading-anchor" href="#buy-or-build" aria-label="Link to this section: “Buy or Build?”">##</a>&ldquo;Buy or Build?&rdquo;</h2>
<p>This is one of the questions that people began asking during this time.
The romancing by any number of more or less credible SaaS providers has
been intense.  All offer some form of LLM-based patent workflow
automation.</p>
<p>I developed an aversion to these spammy offers&ndash;which continue
essentially unabated to this day&ndash;and to the COTS products behind them,
some of which are provided by companies with very deep pockets, both
well-established legal software players, and new entrants.  The reasons
for my gut-level response are numerous, and if you don&rsquo;t care, skip this
section.  In no particular order:</p>
<ul>
<li>
<p>I have never needed COTS to access an LLM, because I am comfortable
writing code to access private language model APIs directly.  Nothing
stands between me and the model.  I know, down to the token, exactly
what is being fed into the model, and can reason explicitly about
outputs with zero opacity (and no upcharge).  Need to generate
something specific and bespoke?  Wrap custom prompts in a loop or a
function.  Need to change something?  Add new functionality?  I have
access to the same agentic coding tools the COTS vendors do, and can
knock features out in an afternoon.  Or an hour.  Or less.  (More on
this in short order.) I&rsquo;ve been accused of &ldquo;vibe coding&rdquo;, and I am
guilty as charged. I&rsquo;m in <a href="https://www.calebleak.com/posts/dog-game/">good company</a>.</p>
</li>
<li>
<p>Because the COTS patent tools are not programming environments (by
definition and design), they are not flexible enough to accommodate all
use cases.  This level of control isn&rsquo;t for everyone, but it&rsquo;s
unaddressed, and probably unaddressable by COTS software.  Tooling
created for <em>all patent attorneys at all law firms</em> attempts to be all
things to everyone, and does a mediocre job at everything.</p>
</li>
<li>
<p>LLM systems are already non-deterministic by default, which makes
reasoning about their outputs a hard problem.  The <em>last</em> thing I want
is well-intentioned minders of a walled garden adding more layers of
uncertainty to the process.  I have heard repeatedly from other
frustrated practitioners riding the LLM rollercoaster that they simply
cannot get COTS software to do what they want it to do, regardless
of how exacting or precise their prompts have become.</p>
</li>
<li>
<p>Apart from reduced flexibility, there are legitimate questions around
the value add of patent COTS over foundation models themselves, which
remains dubious unless ease of use is of paramount importance (which
it is in some cases).  While most foundation models are <a href="https://www.ben-evans.com/benedictevans/2026/2/19/how-will-openai-compete-nkg2x">effectively
identical</a>,
<a href="https://blog.can.ac/2026/02/12/the-harness-problem/">harnesses are critical</a> for
getting useful results.  And because harnesses are critical, they&rsquo;re
the last thing that should be outsourced.</p>
</li>
<li>
<p>No one knows what current patent law AI tool providers, who have at
least theoretical access to some of the juiciest data on the planet,
will do with it in the future.  A federal judge recently ruled that
a criminal defendant&rsquo;s conversations with Claude were <a href="https://www.nytimes.com/2026/02/26/technology/personaltech/ai-complicates-old-internet-privacy-risks.html">not covered by
attorney-client privilege</a>.
Information shared with publicly-available LLMs appears to be a law
enforcement treasure trove, on the order of networked automatic
license plate readers or genetic ancestry databases in terms of its
utility in building criminal cases.  In that climate, introducing
third party risk seems unwise, even if the parallel is a civil-equtiable
context.</p>
</li>
<li>
<p>FOMO is not a reason.  The Citrini/Shah paper linked below reads like alarmist
bullshit, and some of it is, but the AI-Driven Economic Feedback Loop
is 100% real.  COTS adoption feels a lot more like following than
leading.</p>
</li>
<li>
<p>Last but not least, there&rsquo;s the issue of VC&rsquo;s overt disintermediation of a
proud legal tradition with roots reaching back to the founding of the
country.  Not all AI tools are VC backed, but I think it&rsquo;s
shortsighted to assist in this process by being a passive consumer of
COTS patent AI software.  I&rsquo;m not really interested in helping to
<a href="https://www.wsj.com/lifestyle/careers/ai-knowledge-capture-employees-a69a0e1c">train my replacement</a>.</p>
</li>
</ul>
<p>It felt very good to get all of that off my chest, and I hope you do not
feel personally attacked, dear reader.  I think it&rsquo;s important, since
I&rsquo;m discussing my vocation, to remind you that this blog represents <strong>my
opinion only</strong>, and I do not speak for anyone else (see the disclaimer,
below).  However, I think this is important context for where we&rsquo;re
headed.</p>
<p>Assuming patent COTS tools are an <em>antipattern</em> for the Patent
Programmer-Practitioner, what does that leave one to do?</p>
<h2 id="the-real-mackay"><a class="heading-anchor" href="#the-real-mackay" aria-label="Link to this section: The Real MacKay">##</a>The Real MacKay</h2>
<p>This is really a blog post about how LLM technology is truly
<a href="https://en.wikipedia.org/wiki/Clarke%27s_three_laws">indistinguishable from magic</a>, and how
embracing it over the past few years has given me a Christmas
morning-like excitement that I haven&rsquo;t felt about a technology since I
started teaching myself RedHat Linux in 2003.  Before that I&rsquo;d probably
have to revisit the first few months I spent logging on to AOL in the
early &rsquo;90s to find similar enthusiasm for a technology.  As far as
digital technologies go, LLMs are <a href="https://en.wikipedia.org/wiki/The_real_McCoy">the Real
McCoy</a>.</p>
<p>And <a href="https://shumer.dev/something-big-is-happening">a lot</a> has been written
recently about the disruption posed by &ldquo;AI.&rdquo;  I use the term advisedly, <a href="https://www.todayintabs.com/p/a-i-isn-t-people">as one
should</a>&ndash;as Rusty Foster
correctly points out, <em>AI isn&rsquo;t people</em>, and anthropomorphizing
generative AI in the form of LLMs can be a costly category
error, because it blurs the line between a piece of software and a human
being.  Yet some of the more hyped up prose implies that this is a
distinction without a difference, because LLM output &ldquo;<a href="https://shumer.dev/something-big-is-happening">quality has
reached a point where many professionals can&rsquo;t distinguish [it] from
human work</a>.&rdquo; But &ldquo;many
professionals&rdquo; isn&rsquo;t the same as &ldquo;all.&rdquo; It&rsquo;s certainly not &ldquo;all patent
examiners.&rdquo;</p>
<p>If you are looking for <a href="https://www.theregister.com/2026/02/16/semantic_ablation_ai_writing/">semantically
ablated</a>
text, you&rsquo;ll find mounds of it.  The syntax hallmarks of AI slop are
<a href="https://en.wikipedia.org/wiki/Wikipedia:Signs_of_AI_writing">unmistakable</a>.
You might not care if you are booking a plane ticket.  But if you are
drafting a patent claim, you should.</p>
<p>So while they are the Real McCoy, at this point, it&rsquo;s probably also correct, especially if you are using them in the practice of law, to think of LLMs as
<a href="https://dl.acm.org/doi/10.1145/3442188.3445922">stochastic parrots</a> and <a href="https://www.newyorker.com/tech/annals-of-technology/chatgpt-is-a-blurry-jpeg-of-the-web">blurry JPEGs of
reality</a>,
and act accordingly.  There are <a href="https://maggieappleton.com/ai-dark-forest#2-be-original-critical-and-sophisticated">much more colorful descriptors</a>, if you wish.</p>
<p>Despite their rough edges, LLMs are the best learning platform humanity
has ever assembled, apart from other humans, and are lowering the
innovation bar across the board, in every domain you can think of,
including <a href="https://www.theatlantic.com/technology/2026/02/ai-math-terrance-tao/686107/">mathematics</a>.</p>
<p>In my case, it&rsquo;s motorcycles.  At least this quarter.  I decided to
start work on an antique rehabilitation project, and have
recently used LLMs to teach myself about bonded titles (joke&rsquo;s on me),
4-cylinder carburetor rebuilding, and 3D printing.  These are topics
about which I knew next to nothing, until 45 days ago.</p>
<p>My cover story is that I can use the bike to teach my kids about
engines.  In connection with this we recently visited the <a href="https://cucfablab.web.illinois.edu/">UIUC Fab
Lab</a> (shoutout to Michael and co.)
intending to use their 3D scanner for a part that would be $50 on eBay.
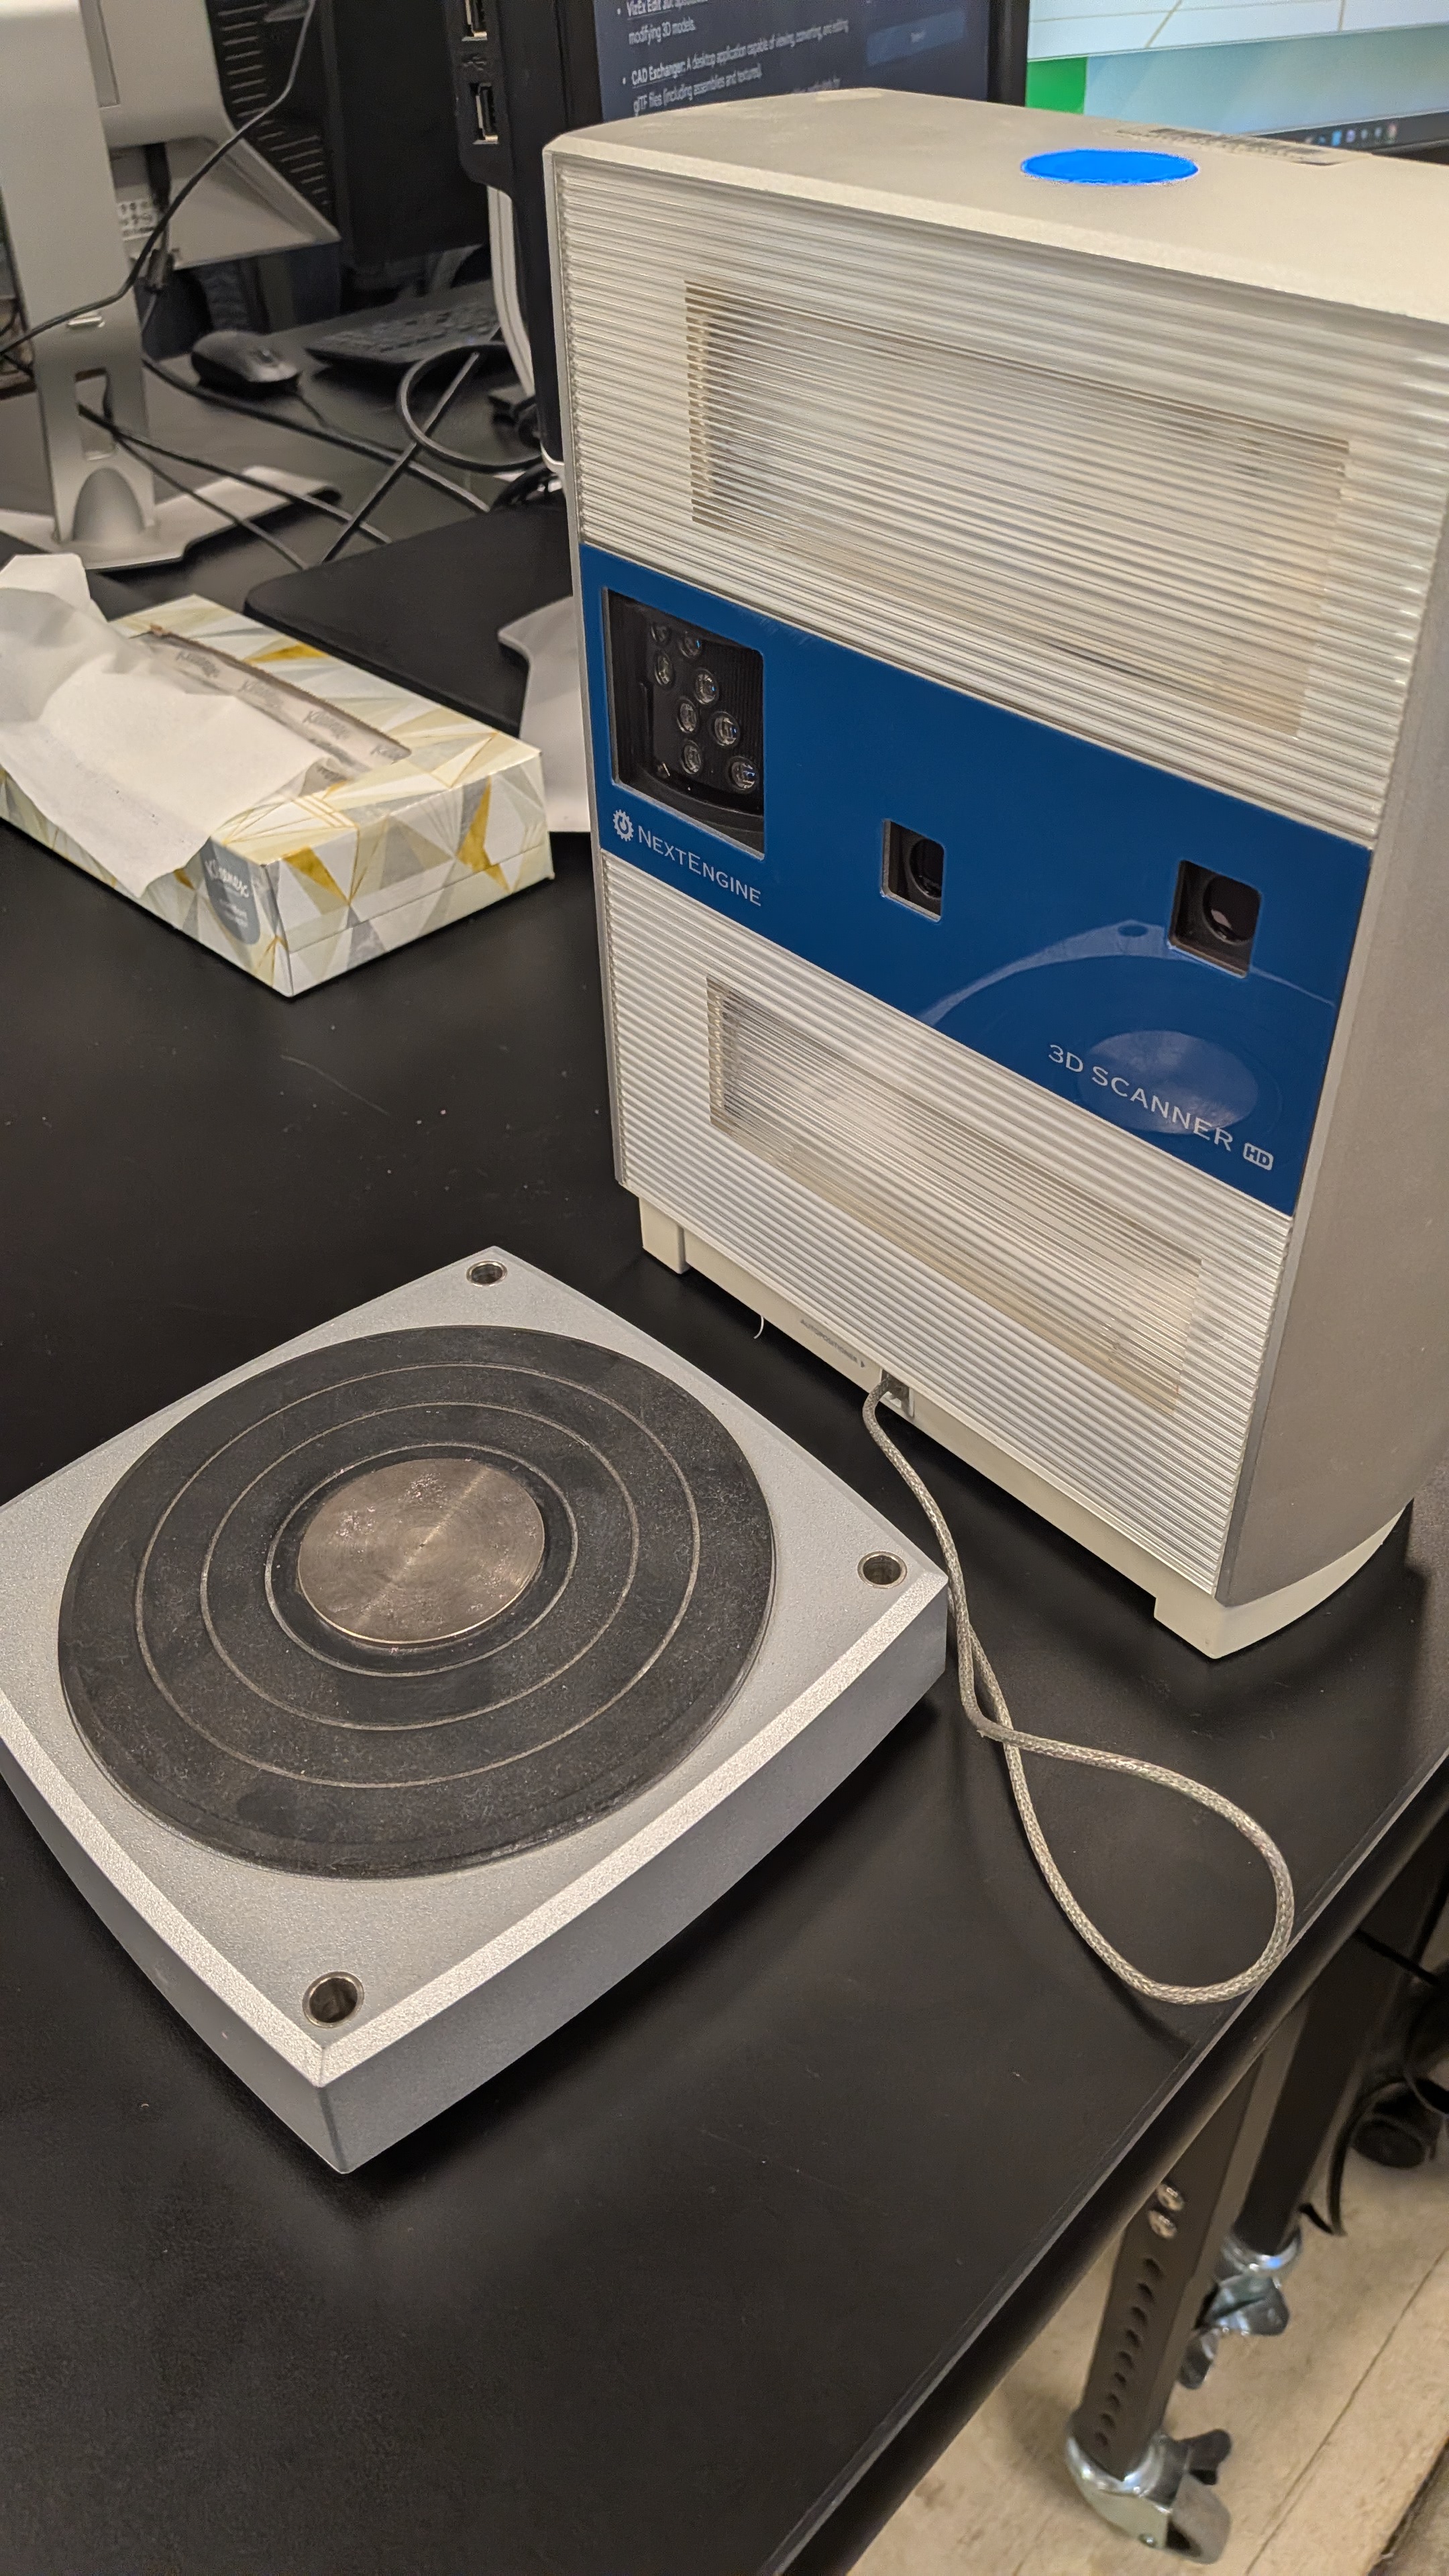
It turns out that the 3D scanner device manufacturer had gone poof,
along with the software for it.</p>
<figure class="blog-photo"><img src="/assets/img/nextengine.jpg" alt="NextEngine 3D Scanner HD" title="NextEngine 3D Scanner HD" loading="lazy" decoding="async" width="1200"><figcaption>NextEngine 3D Scanner HD</figcaption></figure>

<p>Undeterred, we fired up
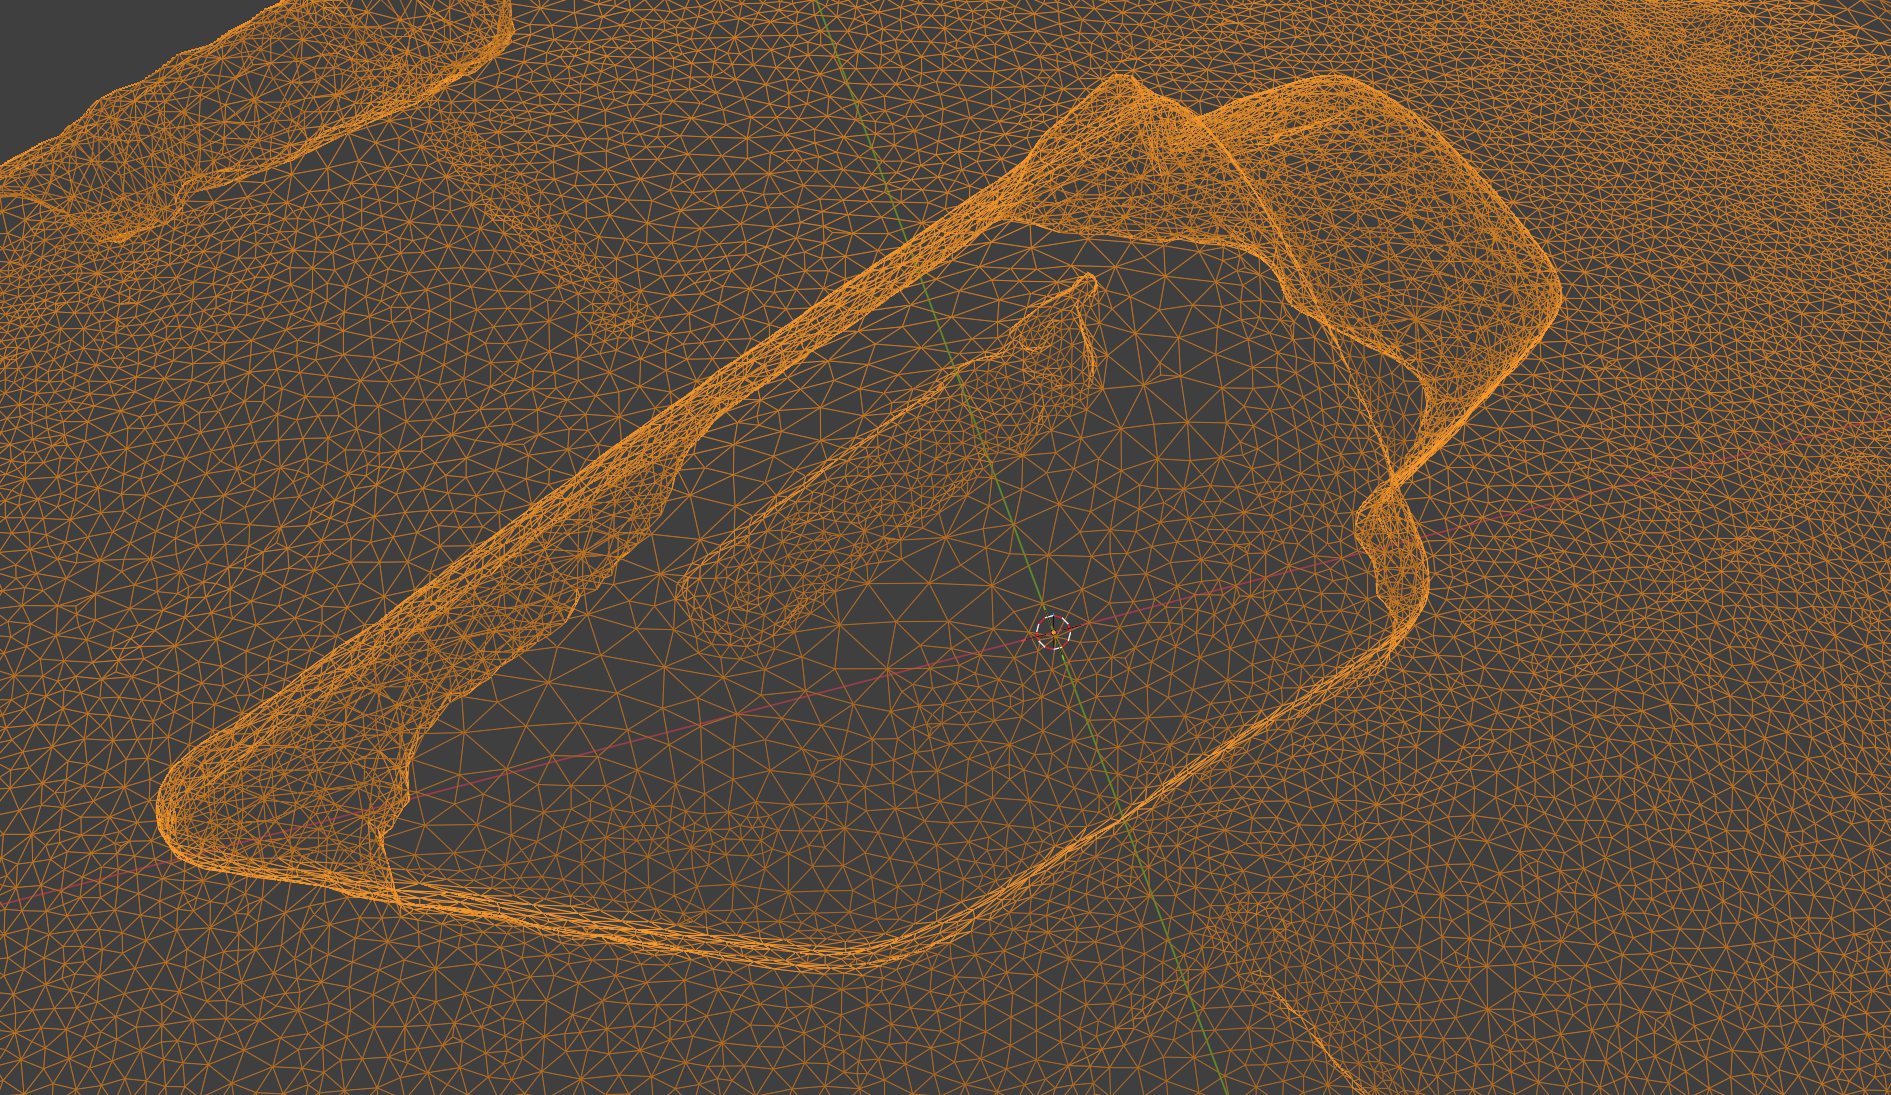
<a href="https://poly.cam/">Polycam</a>&ndash;an amazing piece of software in its own
right&ndash;and were able to quickly capture a 3D model of the complex part
we wanted to print, in glTF 2.0, using our phones.  We then loaded that
file into <a href="https://www.blender.org/">Blender</a> (this decision was made
for us, because glTF is the only free export format of polycam, and
Blender supports glTF well) and are now well on our way to learning
enough Blender to get useful 3D prints, with almost no trial and
error or RTFM.</p>
<p>It&rsquo;s worth pausing to appreciate that this entire sequence of events
is something I would never have had time for in a non-LLM world.  And
there are 1000 other examples of this type of self-directed learning,
many of which I have taken for granted and already forgotten.</p>
<figure class="blog-photo"><img src="/assets/img/blender.png" alt="Blender" title="Blender" loading="lazy" decoding="async" width="1200"><figcaption>Blender</figcaption></figure>

<p>It&rsquo;s also worth pausing to consider, <strong>what if polycam wasn&rsquo;t a thing?</strong>
What if there wasn&rsquo;t a quick and easy alternative to the defunct 3D
scanner?  Could we have bypassed the NextEngine licensing server by
reflashing the device?  Written replacement firmware?  What would the
solution path look like?  Could we point Claude Opus at it and go make a
sandwich?  Perhaps not entirely, but how much time would that have
saved, compared to cracking it manually?</p>
<p>If there is a problem that needs solving, or an idea about which one has
an inkling, or a project that seems a tad too ambitious, some initiative
plus an LLM makes for a sufficiently more capable/ dangerous human.  I
am <a href="https://minimaxir.com/2026/02/ai-agent-coding/#the-implications-of-my-agentic-successes">not the only
one</a>
whose initial AI skepticism has been won over by recent advances in
<strong>agentic AI discourse</strong>, especially where software is concerned.</p>
<p>Another recent example, beyond motorcycles, is how quickly things I
already know how to do can be significantly sped up.  For some of my
clients, I need to keep up with new small arms technologies and trends
in that industry.  So I created
<a href="https://gunclaims.tilton.co/">GunClaims</a>, a microsite that processes
the entire USPTO patent gazette every Tuesday, classifies the new patent
issuances according to whether they are in the small arms/ammunition
field, and publishes them in an easy-to-read format.</p>
<p>It took me about 8 hours total to put GunClaims together, from
programming to deployment, and testing.  That&rsquo;s pretty amazing velocity
from idea to clockwork execution.  Of course, GunClaims could be done
with any sub-specialty or subject matter interest, and it is far from
perfect.  I only mention it, as one example of the amplification
potential in using LLMs to automate tasks that might otherwise exist
only as mere passing thoughts.</p>
<h2 id="agentic-schmagentic-a-very-complicated-and-nuanced-story"><a class="heading-anchor" href="#agentic-schmagentic-a-very-complicated-and-nuanced-story" aria-label="Link to this section: Agentic Schmagentic (A very complicated and nuanced story)">##</a>Agentic Schmagentic (A very complicated and nuanced story)</h2>
<p>In this moment, we are well on our way in the <strong>agentic</strong> era of the LLM
rollout.  In simple terms, an &ldquo;agentic&rdquo; model refers to one that <em>has
state (memory), access to tools, and which runs in a loop to act
autonomously in furtherance of a goal.</em>  That goal&ndash;which can be
expressed in multi-modal terms&ndash;could be something
like &ldquo;create firmware for this defunct 3D scanner.&rdquo;  Or &ldquo;explain where
this pilot jet goes in relation to the float arm.&rdquo;  Or
&ldquo;draft an office action response&rdquo; or &ldquo;draft a first draft of a patent
application.&rdquo;  However, because <code>$goal</code> can be just about anything,
there has been much <a href="https://ai-2027.com/">rending</a>
<a href="https://www.citriniresearch.com/p/2028gic">of</a>
<a href="https://www.nytimes.com/2026/02/18/opinion/ai-software.html">garments</a>
and outright doomerism over agentic technology (some of which may be correct).
The economic consequences of the transformation to an agentic world are <a href="https://www.washingtonpost.com/technology/2026/02/23/ai-economic-growth-gdp-mirage/">less
clear</a>.</p>
<p>Despite this, not everyone believes the sky is falling.  Labor
substitution is <a href="https://davidoks.blog/p/why-im-not-worried-about-ai-job-loss">still difficult</a>, and bottlenecks still exist (often by design).
A more sober <a href="https://github.com/anomalyco/models.dev/pull/1056">report</a> from Citadel
in response to the Citrini piece makes the case that AI is a productivity
shock, not a demand shock, and notes that SWE jobs are rapidly rising
while human demand for new technologies remains elastic.
Others have observed that <a href="https://www.ivanturkovic.com/2026/01/22/history-software-simplification-cobol-ai-hype/">software developers are basically
cockroaches</a>.</p>
<p>I think Terry Tao gets it right, <a href="https://www.theatlantic.com/technology/2026/02/ai-math-terrance-tao/686107/">discussing</a>
the application of Generative AI to the <a href="https://github.com/teorth/erdosproblems/wiki/AI-contributions-to-Erd%C5%91s-problems">Erdős
Problems</a>:</p>
<blockquote>
<p>There&rsquo;s a big crowd of people who really, really want AI success
stories. And then there’s an equal and opposite crowd of people who
want to dismiss all AI progress. And what we have is a very
complicated and nuanced story in between.</p>
</blockquote>
<p>Regardless of which prognostications are correct, the truth of the
matter is that the agentic LLMs are already extremely impressive, in
certain narrow bands.  Thus, there does not seem to be any question that
LLM tech will be disruptive of existing white collar labor practices.
The question is one of degree.  But the first and most notable disruption to
date has been to code generation, a.k.a. computer programming, a.k.a.
software engineering.</p>
<h2 id="jetpacks-baby"><a class="heading-anchor" href="#jetpacks-baby" aria-label="Link to this section: Jetpacks, Baby!">##</a>Jetpacks, Baby!</h2>
<p>Returning to my Git commit above, for the first year or so of developing
OS, I was writing code as I had for 20 years &ndash; in a text editor, with
code assistant niceties (syntax highlighting, static analysis, autocomplete
and an LSP server). A year later, I had worked up the nerve to use ChatGPT to
explore coding ideas piecemeal, evaluating the outputs and manually
copy-pasting them into my editor, before cleaning them up and testing
them. At this point, I was still facing down the same trepidation and
unease I had felt when first touching these models, something that <a href="https://mariozechner.at/posts/2025-11-30-pi-coding-agent/">I
was</a> <a href="https://carlkolon.com/2026/02/27/engineering-747-coding-agents/">not alone</a> in feeling.  That rollercoaster looks massively tall&hellip;</p>
<p>Mid-October of last year marked the agentic inflection point in my use
of LLMs.  After hearing a friend rave about
<a href="https://cursor.com/">Cursor</a>, I finally broke down and installed Visual
Studio so I could dip my toes into
<a href="https://claude.com/product/claude-code">Claude</a> and
<a href="https://openai.com/codex/">Codex</a>.  Whoosh! This rollercoaster has a
jetpack!  I was hooked.</p>
<p>&hellip;And that was an older version of Codex (which I settled on using, due
to inertia and familiarity).  Newer versions of Claude/Codex are even
more impressive, and are good at making (sometimes improved)
copies of other highly complex things, like <a href="https://blog.cloudflare.com/vinext/">JavaScript
frameworks</a> and <a href="https://www.anthropic.com/engineering/building-c-compiler">C
Compilers</a>.
They can also do this very swiftly, compared to traditional software
development practices.</p>
<p>Chris Lattner&rsquo;s
<a href="https://www.modular.com/blog/the-claude-c-compiler-what-it-reveals-about-the-future-of-software">analysis</a>
of the Anthropic C compiler project is quite revealing of current
agentic capabilities.  The technical capability conclusions of that
article are worth internalizing.  I discuss them in more detail below.
More directly relevant to the practice of patent law, Chris noted:</p>
<blockquote>
<p>IP Law and Proprietary Software Moats</p>
<p>The Claude C Compiler also raises important yet uncomfortable questions
about intellectual property. If AI systems trained on decades of
publicly available code can reproduce familiar structures, patterns, and
even specific implementations, where exactly is the boundary between
learning and copying?</p>
</blockquote>
<p>This is an excellent observation, and an illustration of an issue
(LLM-based copying) that has been on IP professionals&rsquo; radars for a
while now. Similar concerns touched off (another)
<a href="https://techcrunch.com/2026/02/25/salesforce-ceo-marc-benioff-this-isnt-our-first-saaspocalypse/">SaaS-pocalypse</a>
in markets over the last few weeks.  Suffice to say, IP law is rapidly evolving in
this area, and markets are&ndash;rightfully&ndash;jittery, as agentic capabilities
have arrived.</p>
<h2 id="of-vibe-drafters-and-agentic-patent-practitioners-or-how-i-am-using-agentic-ai-in-patent-practice"><a class="heading-anchor" href="#of-vibe-drafters-and-agentic-patent-practitioners-or-how-i-am-using-agentic-ai-in-patent-practice" aria-label="Link to this section: Of Vibe Drafters and Agentic Patent Practitioners, or How I Am Using Agentic AI in Patent Practice">##</a>Of Vibe Drafters and Agentic Patent Practitioners, or How I Am Using Agentic AI in Patent Practice</h2>
<p>So how am I using agentic AI in patent practice?</p>
<p>The shortest answer is the following analogy:</p>
<pre tabindex="0"><code>coding agents : software engineering :: drafting agents : patent practice
</code></pre><p>The slightly longer answer involves a two-part experiment:</p>
<ol>
<li>
<p>Find a software practitioner blog post about how they are using
agentic AI for software development.</p>
</li>
<li>
<p>apply the following word replacements:</p>
<table>
	<thead>
			<tr>
					<th>from -&gt;</th>
					<th>to</th>
			</tr>
	</thead>
	<tbody>
			<tr>
					<td>code</td>
					<td>draft</td>
			</tr>
			<tr>
					<td>software</td>
					<td>patent</td>
			</tr>
			<tr>
					<td>programmer, engineer, etc.</td>
					<td>patent practitioner</td>
			</tr>
	</tbody>
</table>
</li>
</ol>
<p>The result of this word replacement experiment is likely as good an answer
to the question as any other.</p>
<p>Take for example the introductory paragraphs of Simon Willison&rsquo;s
recent <a href="https://simonwillison.net/2026/Feb/23/agentic-engineering-patterns/">post</a>
on Agentic Engineering Patterns (strikethrough and underline showing above substitutions):</p>
<blockquote>
<p>Writing about Agentic <del>Engineering</del> <ins>Patent Practice</ins> Patterns</p>
<p>I’ve started a new project to collect and document Agentic
<del>Engineering</del> <ins>Patent Practice</ins> Patterns—<del>coding</del> <ins>drafting</ins>
practices and patterns to help get the best results out of this new
era of <del>coding</del> <ins>drafting</ins> agent development we find ourselves
entering.</p>
<p>I’m using Agentic <del>Engineering</del> <ins>Patent Practice</ins> to refer to
building <del>software</del> <ins>patents</ins> using <del>coding</del> <ins>drafting</ins>
agents—tools like Claude Code and OpenAI Codex, where the defining
feature is that they can both generate and execute <del>code</del>
<ins>a draft</ins>—allowing them to test that <del>code</del> <ins>draft</ins> and iterate on
it independently of turn-by-turn guidance from their human supervisor.</p>
<p>I think of vibe <del>coding</del> <ins>drafting</ins> using its original definition of
<del>coding</del> <ins>drafting</ins> where you pay no attention to the <del>code</del>
<ins>draft</ins> at all, which today is often associated with
<del>non-programmers</del> <ins>non-practitioners</ins> using LLMs to write
<del>code</del> <ins>a draft</ins>.</p>
<p>Agentic <del>Engineering</del> <ins>Patent Practice</ins> represents the other end of
the scale: professional <del>software engineers</del> <ins>patent practitioners</ins>
using <del>coding</del> <ins>drafting</ins> agents to improve and accelerate their
work by amplifying their existing expertise.</p>
</blockquote>
<p>With sincere apologies to Simon, the rhetorical point here is pretty
clear: that this fun little experiment works so well demonstrates
the near-total convergence between the cognitive tasks of professional
software engineers and patent practitioners, as far as LLM tooling is
concerned.  The only difference is the technological domain, and
credentials.</p>
<p>One caveat/clarification: there are important distinctions between the
instances of coding model providers that are available from given
different tenancy configurations/ paid membership tiers, that are beyond
the scope of this post (except to say, it&rsquo;s essential that vetting and
diligence be done to avoid privilege waiver or other issues).  I am not
endorsing any particular model provider.</p>
<p>I&rsquo;ll be writing more about my free/open source agentic patent software
stack in the coming days, so please stay tuned for that.  For now it
suffices to say, you know you&rsquo;re on the bleeding edge when you are
impatiently patching code to fix bug reports that are only a <a href="https://github.com/anomalyco/models.dev/pull/1056">few hours
old</a>.</p>
<h2 id="merging-but-not-emerging-"><a class="heading-anchor" href="#merging-but-not-emerging-" aria-label="Link to this section: Merging, but Not Emerging (?)">##</a>Merging, but Not Emerging (?)</h2>
<p>Returning to Chris Lattner&rsquo;s piece from about the Claude C compiler, I
suggest that reading it again, but this time, imagine that instead of a C
compiler, he&rsquo;s talking about a patent application drafting system (or
whichever hairy knowledge artifact you please).  Here are some of the
things you might have read in that case, from his main takeaways
(edited using my replacement table above, and graded by me for
anecdotal accuracy):</p>
<ul>
<li>
<p>AI has moved beyond writing small snippets of drafts and is beginning to
participate in drafting large patent applications (True)</p>
</li>
<li>
<p>AI is crossing from local draft generation into global practitioner
participation (True)</p>
</li>
<li>
<p>Our legal apparatus frequently lags behind technology progress, and AI
is pushing legal boundaries. Is private patent practice cooked? (Maybe)</p>
</li>
<li>
<p>Good drafting depends on judgment, communication, and clear
abstraction. AI has amplified this. (True)</p>
</li>
<li>
<p>AI drafting is automation of implementation, so design and stewardship
become more important. (True)</p>
</li>
<li>
<p>Manual rewrites and translation work are becoming AI-native tasks,
automating a large category of drafting effort. (True)</p>
</li>
<li>
<p>AI, used right, should produce better drafts, provided humans actually
spend more energy on architecture, design, and innovation. (True)</p>
</li>
<li>
<p>Architecture documentation has become infrastructure as AI systems
amplify well-structured knowledge while punishing undocumented
systems. (True)</p>
</li>
</ul>
<p>Perhaps the most interesting takeaway of Chris&rsquo;s post (unedited) is that:</p>
<blockquote>
<p>AI systems can internalize the textbook knowledge of a field and apply
it coherently at scale. AI can now reliably operate within established
engineering practice. This is a genuine milestone that removes much of
the drudgery of repetition and allows engineers to start closer to the
state of the art. But it also highlights an important limitation of
this work:</p>
<p>Implementing known abstractions is not the same as inventing new
ones. I see nothing novel in this implementation.</p>
</blockquote>
<p>Change &ldquo;engineering&rdquo; to &ldquo;lawyering&rdquo; or &ldquo;accountancy&rdquo; and see how it
feels. I think it&rsquo;s about right, including that agentic systems
are&ndash;currently&ndash;pattern-limited, and lacking truly creative emergent
intelligence.</p>
<p>Chris then hits the nail directly on the head:</p>
<blockquote>
<p>As implementation becomes cheaper, the role of engineers shifts upward.
The scarce skills become choosing the right abstractions, defining
meaningful problems, and designing systems that humans and AI can evolve
together. <strong>This will increasingly blur the boundary between software
engineering and product thinking.</strong></p>
</blockquote>
<p>The merger will not be televised.</p>
<h2 id="its-all-one-song"><a class="heading-anchor" href="#its-all-one-song" aria-label="Link to this section: It’s All One Song">##</a>It&rsquo;s All One Song</h2>
<p>The merger between software development and patent practice (and
other knowledge tasks) shows itself in funny ways.</p>
<p>Example: I was recently offered a guest column by a major financial
publication, and I spent a couple of days thinking about the topic and
writing about my perspective.  The copy was like this, but shorter and
a lot more sterile.  It used the phrase &ldquo;jagged edge&rdquo; (with attribution).</p>
<p>The editor refused to publish it, saying my essay was &ldquo;duplicative of
recently published content.&rdquo;  At first I thought I was being accused of
plagiarism, but then I decided to ask for the editor for clarification.
What they <em>really</em> wanted, they said, was something more focused on &ldquo;my
specific experience in developing an AI solution, along with lessons
learned/challenges observed that other AI innovators can appreciate.&rdquo;</p>
<p>Well, this is that specific experience, in rando blog form, and the
lesson learned/ challenge observed is that <strong>we&rsquo;re all on the same
AI forevercoaster, and that wasn&rsquo;t my original idea, either.</strong> On
the off chance you&rsquo;re that editor, I hope you don&rsquo;t find this content
overly duplicative, but also, who needs an editor (!?) and, you&rsquo;re
welcome (not getting those non-billable hours back).</p>
<h2 id="agentic-patent-practice-inferences-from-other-disciplines"><a class="heading-anchor" href="#agentic-patent-practice-inferences-from-other-disciplines" aria-label="Link to this section: Agentic Patent Practice: Inferences from Other Disciplines">##</a>Agentic Patent Practice: Inferences from Other Disciplines</h2>
<p>Having established that agentic patent practice is a horse of a
different color, but still a horse, there are endless lessons that we
Agentic Patent Practitioners can take away from the &ldquo;first wavers&rdquo;&ndash;those
whose disciplines have been so profoundly affected by the rise of agentic
machines&ndash;and their useful adaptations.  The aforementioned <a href="https://simonwillison.net/guides/agentic-engineering-patterns/">agentic
engineering guide</a>
discusses several additional principles and patterns that are directly
applicable to Agentic Patent Practice, and is a good place to start.</p>
<p><a href="https://martinfowler.com/articles/reduce-friction-ai/knowledge-priming.html">&ldquo;Knowledge Priming&rdquo;</a>
is another useful pattern, that involves systematically parameterizing the agent with information it needs to generate better outputs.</p>
<p><a href="https://gist.github.com/dollspace-gay/d8d3bc3ecf4188df049d7a4726bb2a00">Several</a>
<a href="https://github.com/shanraisshan/claude-code-best-practice">others</a>
<a href="https://gist.github.com/dollspace-gay/d8d3bc3ecf4188df049d7a4726bb2a00">have</a>
written more or less formally about how they are using agentic AI
systems more systematically to improve results.</p>
<p>Terry Tao is instructive here, too.  He <a href="https://www.theatlantic.com/technology/2026/02/ai-math-terrance-tao/686107/">observed</a>
that current models are successful at eliminating tedium and searching
the long tail of problem spaces, and at enabling population-level
analysis, while expressing healthy skepticism of turnkey agentic
workflows:</p>
<blockquote>
<p>[A] lot of AI companies have this obsession with push-of-a-button,
completely autonomous workflows where you give your task to the AI,
and then you just go have a coffee, and you come back and the problem
is solved. That’s actually not ideal. With difficult problems, you
really want a conversation between humans and AI. And the AI companies
are not really facilitating that.</p>
</blockquote>
<p>This rings true.</p>
<p>My overarching point is that patent practitioners should be reading the
experiences and absorbing learning from those who have gone before, and
porting their adaptations to our practice.</p>
<h2 id="riding-the-ai-forevercoaster-off-into-the-sunset-"><a class="heading-anchor" href="#riding-the-ai-forevercoaster-off-into-the-sunset-" aria-label="Link to this section: Riding the AI Forevercoaster off into the Sunset (?)">##</a>Riding the AI Forevercoaster off into the Sunset (?)</h2>
<p>Lately I&rsquo;ve been thinking about how the ranking of app tokens in my MFA
app determines the order of importance of each app to my life.  There
are a few token providers above my LLM providers on my phone, but the
LLMs are close to the top&ndash;ahead of Amazon, Cloudflare, Firefox, Github, and
social media, to name a few.</p>
<p>If your employer is not already forcing you to use AI, they probably <a href="https://www.wsj.com/tech/ai/tech-firms-arent-just-encouraging-their-workers-to-use-ai-theyre-enforcing-it-d43ebf84">will be
soon</a>.
Indeed, if you are working a white collar job, and not retiring soon,
facility with AI is <a href="https://nolanlawson.com/2026/02/07/we-mourn-our-craft/">not something you&rsquo;ll be able to avoid</a>.</p>
<p>It&rsquo;s also true that AI makes everyone work more, and harder.  As
Siddhant Khare <a href="https://siddhantkhare.com/writing/ai-fatigue-is-real">puts
it</a>,</p>
<blockquote>
<p>AI reduces the cost of production but increases the cost of
coordination, review, and decision-making. And those costs fall
entirely on the human.</p>
</blockquote>
<p>Recent <a href="https://hbr.org/2026/02/ai-doesnt-reduce-work-it-intensifies-it">research</a>
suggests essentially the same thing: that unfettered AI adoption can
lead to &ldquo;cognitive fatigue, burnout and weakened decision-making.&rdquo;
Khare makes some other good points about the inherent cognitive
fatigue brought about by working with nondeterministic systems, the
FOMO treadmill and prompt yak shaving.  His solutions to these
problems, and more, are worth reading.  As are Steve Yegge&rsquo;s recent
thoughts on what he calls the <a href="https://steve-yegge.medium.com/the-ai-vampire-eda6e4f07163">AI Vampire</a>.
And those of Jennifer Moore on <a href="https://jenniferplusplus.com/what-is-a-token/">anchoring and vigilance</a>.</p>
<p>These articles and others about <a href="https://tomwojcik.com/posts/2026-02-15/finding-the-right-amount-of-ai/">cognitive debt</a>
make the point that the adoption of AI has forced many software
developers who were formerly &ldquo;doers&rdquo; into &ldquo;reviewers.&rdquo;  The same is true
in the law. Gone are the days of keyboard jockeying, searching a
thesaurus for the perfect next word while grinding out paragraphs of
prose.  Editing and revision are the main modalities now, even for newer
practitioners.  If you have used AI for even a short time, this is old
hat.</p>
<p>For people just entering the practice, Terry Tao is a typical font of <a href="https://www.theatlantic.com/technology/2026/02/ai-math-terrance-tao/686107/">useful wisdom</a>:</p>
<blockquote>
<p>[Math] problems are like distant locations that you would hike to. And
in the past, you would have to go on a journey. You can lay down trail
markers that other people could follow, and you could make maps.  AI
tools are like taking a helicopter to drop you off at the site. You
miss all the benefits of the journey itself. You just get right to the
destination, which actually was only just a part of the value of
solving these problems.</p>
</blockquote>
<p>This is apt, and I would encourage newer practitioners to be wary of helicopter
rides and other forms of
<a href="https://www.joanwestenberg.com/how-convenience-kills-curiosity/">convenience</a>,
lest they fall into the <a href="https://htmx.org/essays/yes-and/">Sorcerer&rsquo;s Apprentice
Trap</a>.</p>
<p>Better to stay firmly belted in to your coaster seat, keeping your arms
and legs inside the ride at all times.</p>
<figure class="blog-photo"><img src="/assets/img/hulk.jpg" alt="Hulk" title="Hulk" loading="lazy" decoding="async" width="1200"><figcaption>Hulk</figcaption></figure>

]]></content><author><name>Noah K. Tilton</name></author><category term="patents"/><category term="software"/><category term="ai"/><summary type="html">This is a longish, and long-overdue post with some of my thoughts (aka lightly edited brain dump/screed) on developing and using agentic AI for patent practice.
##How it Started commit 59014c091efa219987779af1c0844c4aa0304ee0 Author: Noah K. Tilton &lt;code@tilton.co&gt; Date: Sun Jan 7 17:00:08 2024 -0600 blah I made this initial commit on a Sunday afternoon with a listless message I use when I’m too lazy or tired to type a descriptive one. This is not usually a problem, because most of the software I write is not intended to be read or used by others. I have not worked as a professional software developer for over a decade, and as a patent prosecution partner with a robust practice, I still do not.</summary></entry><entry><title type="html">Federal Circuit Invalidates “Device-Tailored Content Delivery” Patents Under § 101</title><link href="https://blog.tilton.co/2026/02/12/federal-circuit-invalidates-device-tailored-content-delivery-patents-under-101.html" rel="alternate" type="text/html" title="Federal Circuit Invalidates “Device-Tailored Content Delivery” Patents Under § 101"/><published>2026-02-12T00:00:00-06:00</published><updated>2026-07-24T10:55:39-05:00</updated><id>https://blog.tilton.co/2026/02/12/federal-circuit-invalidates-device-tailored-content-delivery-patents-under-101</id><content type="html" xml:base="https://blog.tilton.co/2026/02/12/federal-circuit-invalidates-device-tailored-content-delivery-patents-under-101.html"><![CDATA[<p><a href="https://www.cafc.uscourts.gov/opinions-orders/24-1669.OPINION.2-9-2026_2644908.pdf"><strong>GoTV Streaming, LLC v. Netflix, Inc., Nos. 2024-1669, 2024-1744 (Fed. Cir. Feb. 9, 2026)</strong></a></p>
<p>On February 9, 2026, the U.S. Court of Appeals for the Federal Circuit reversed
a judgment and jury damages award against Netflix, holding that the asserted
claims of three related GoTV Streaming patents (U.S. Patent Nos. 8,478,245,
8,989,715, and 8,103,865) are <strong>patent-ineligible under 35 U.S.C. § 101</strong>. The
court concluded the claims are directed to an abstract
idea (using a generic template of specifications and then tailoring those
specifications to a user device’s constraints using conventional server/ network
operations) and do not recite an inventive concept sufficient to transform
that idea into patent-eligible subject matter.</p>
<p>Although the court also reversed the district court’s indefiniteness ruling as
to one claim phrase, the § 101 holding was dispositive and the Federal Circuit
directed entry of judgment for Netflix, erasing a significant jury verdict in
the process.</p>
<figure class="blog-photo"><a href="https://patents.google.com/patent/US8989715B2" target="_blank" rel="noopener noreferrer"><img src="/assets/img/US08989715-20150324-D00001.png" alt="FIG. 1A &#39;715" title="FIG. 1A &#39;715" loading="lazy" decoding="async" width="1200"></a><figcaption>FIG. 1A &#39;715</figcaption></figure>

<hr>
<h2 id="the--101-holding-abstract-idea--conventional-implementation"><a class="heading-anchor" href="#the--101-holding-abstract-idea--conventional-implementation" aria-label="Link to this section: The § 101 Holding: Abstract Idea &#43; Conventional Implementation">##</a>The § 101 Holding: Abstract Idea + Conventional Implementation</h2>
<h3 id="the-claimed-concept-as-treated-by-the-court"><a class="heading-anchor" href="#the-claimed-concept-as-treated-by-the-court" aria-label="Link to this section: The Claimed Concept (as Treated by the Court)">###</a>The Claimed Concept (as Treated by the Court)</h3>
<p>GoTV’s patents are generally directed to delivering application content to
wireless devices by having a server:</p>
<ul>
<li>receive a device request (including device type);</li>
<li>generate a <strong>wireless-device-generic template</strong> (a non-device-specific set of display specifications);</li>
<li>send a <strong>custom configuration</strong> (look-and-feel data) to the device; and</li>
<li>generate and send a <strong>page description</strong> based on the generic template and the device’s capabilities, containing at least one “discrete low level rendering command” in device-generic syntax but within the device’s rendering capability.</li>
</ul>
<p>For eligibility purposes, GoTV treated claim 1 of the ’865 patent as
representative, and the court focused its analysis accordingly, finding all
asserted claims invalid for the same reasons.</p>
<hr>
<h2 id="alice-step-one-directed-to-an-abstract-idea"><a class="heading-anchor" href="#alice-step-one-directed-to-an-abstract-idea" aria-label="Link to this section: Alice Step One: “Directed to” an Abstract Idea">##</a><em>Alice</em> Step One: “Directed to” an Abstract Idea</h2>
<p>Reversing the District Court&rsquo;s conclusion that the claims were eligible at Step
One, the Federal Circuit held that the representative claim is directed to the
abstract idea of:</p>
<ul>
<li>creating a <strong>template set of specifications</strong> that is generic in at least some respects, and</li>
<li><strong>tailoring</strong> at least one aspect of that template for final production to fit user-specific constraints (here, the requesting device’s capabilities).</li>
</ul>
<p>The court emphasized that this type of templating-and-tailoring concept is a
<strong>familiar, longstanding practice</strong> and remains abstract even when applied to a
particular technological environment (wireless device displays). The claims
were not saved by describing the idea in the vocabulary of networks and mobile
rendering; narrowing the abstract idea to “display content on a wireless
device” did not change the Step One outcome.</p>
<p>Conventionality and technological environment are legitimate <em>Alice</em> Step One inquiries,
and the Federal Circuit in <em>GoTV</em> followed a line of other cases that have
treated “result-based functional language” as a red flag at Step One.  For
example, in <a href="https://www.cafc.uscourts.gov/opinions-orders/16-2531.opinion.10-27-2017.1.pdf"><em>Two-Way Media</em></a>, the court explained that the representative claim
required the functional results of “converting,” “routing,” “controlling,”
“monitoring,” and “accumulating records,” but “does not sufficiently describe
how to achieve these results in a non-abstract way,” and that, at best, the
claimed constructions relied on generic computer components providing only a
generic environment for carrying out the abstract idea.</p>
<p>Likewise, <a href="https://www.cafc.uscourts.gov/opinions-orders/23-2437.OPINION.4-18-2025_2500790.pdf"><em>Recentive</em></a> confirmed that it is proper at Step One to treat claims
as abstract where the claimed “advance” is the use of an already available
technology with its already available basic functions “as a tool” and where the
claims disclose only that the technology is used in a new environment—and it
adds that simply performing a task humans previously did “with greater speed
and efficiency” (without improved computer techniques) does not change the
eligibility outcome (expressly noting this point applies “[w]hether the issue is
raised at step one or step two”).</p>
<h3 id="no-concrete-computer-improvement"><a class="heading-anchor" href="#no-concrete-computer-improvement" aria-label="Link to this section: No Concrete “Computer Improvement”">###</a>No Concrete “Computer Improvement”</h3>
<p>GoTV argued the claims were directed to a computer/network improvement, but the
court rejected that framing because the claims:</p>
<ul>
<li>do <strong>not</strong> recite new or improved hardware (server, device, or network);</li>
<li>do <strong>not</strong> improve the wireless device’s rendering process (the device’s rendering capability is assumed and merely accommodated);</li>
<li>do <strong>not</strong> improve ordinary computer operations such as receiving, storing, processing, outputting, and transmitting data.</li>
</ul>
<p>Instead, the claim uses conventional computing and networking as tools to
perform the templating-and-tailoring idea.</p>
<h3 id="technical-labels-didnt-change-the-analysis"><a class="heading-anchor" href="#technical-labels-didnt-change-the-analysis" aria-label="Link to this section: “Technical” Labels Didn’t Change the Analysis">###</a>“Technical” Labels Didn’t Change the Analysis</h3>
<p>The court treated terms GoTV relied on (e.g., “wireless device generic
template,” “custom configuration,” “page description,” and “rendering
command”) as describing <strong>packages of information</strong> rather than specific
technological structures or mechanisms that improve how computers or networks
operate. In the court’s view, these terms did not provide the missing “how”
needed to show a concrete improvement to computer functionality, as opposed to
functional results.</p>
<hr>
<h2 id="alice-step-two-no-inventive-concept"><a class="heading-anchor" href="#alice-step-two-no-inventive-concept" aria-label="Link to this section: Alice Step Two: No Inventive Concept">##</a><em>Alice</em> Step Two: No Inventive Concept</h2>
<p>Having found the claims directed to an abstract idea, the court proceeded to
Step Two and held there was no inventive concept that made the claims
“significantly more” than the abstract idea.</p>
<p>Key points driving the Step Two conclusion:</p>
<ul>
<li>The claims rely on <strong>result-focused, functional language</strong> (e.g., generate a
template, tailor based on device capability, send descriptions/configurations)
without specifying <strong>how</strong> tailoring is performed in a nonconventional way.</li>
<li>The claims invoke <strong>ordinary server/network functions</strong> (receiving requests,
assembling information, transmitting data) without any claimed improvement in
how those functions are carried out.</li>
<li>Any asserted improvements in speed or efficiency were attributed to using
conventional computers and networks, which the court reiterated is not enough
to confer eligibility.</li>
<li>The court discounted reliance on GoTV’s expert declaration because
conclusory assertions about inventiveness or performance gains, untethered
to concrete claim limitations, do not supply an inventive concept.</li>
</ul>
<hr>
<h2 id="what-this-means-in-practice"><a class="heading-anchor" href="#what-this-means-in-practice" aria-label="Link to this section: What This Means in Practice">##</a>What This Means in Practice</h2>
<h3 id="1-adapt-content-to-device-capabilities-remains--101-sensitive"><a class="heading-anchor" href="#1-adapt-content-to-device-capabilities-remains--101-sensitive" aria-label="Link to this section: 1) “Adapt content to device capabilities” remains § 101-sensitive">###</a>1) “Adapt content to device capabilities” remains § 101-sensitive</h3>
<p>This decision reinforces that claims centered on <strong>tailoring content/display
specifications</strong> to device constraints are vulnerable when they read as merely
gathering information, generating a template, tailoring the template, sending
it and transmitting it, all implemented using conventional computing and
networking.</p>
<h3 id="2-eligibility-turns-on-the-how-not-the-what"><a class="heading-anchor" href="#2-eligibility-turns-on-the-how-not-the-what" aria-label="Link to this section: 2) Eligibility turns on the “how,” not the “what”">###</a>2) Eligibility turns on the “how,” not the “what”</h3>
<p>If the “advance” is adaptation/customization (templates, tailoring,
optimization, personalization, ML-based selection), claims need to include the
<strong>how</strong>, in the form of a concrete mechanism (specific algorithmic steps, data
structure constraints, protocol-level changes, or a defined improvement to
computer/network operation). Otherwise, a court can characterize the claim as
result-oriented and “tool use” at Step One.</p>
<p>Even when claims use jargony language (&ldquo;templates&rdquo;, &ldquo;configurations&rdquo;, &ldquo;rendering
commands&rdquo;), the court will look for a <strong>specific mechanism</strong> or a <strong>concrete
improvement</strong> in computer/network functionality, rather than a desired outcome
recited at a high level.  For the prosecutors in the crowd, the appropriate
claim drafting mantra is &ldquo;how, not what.&rdquo;</p>
<h3 id="3-step-two-requires-more-than-efficiency-rhetoric"><a class="heading-anchor" href="#3-step-two-requires-more-than-efficiency-rhetoric" aria-label="Link to this section: 3) Step two requires more than efficiency rhetoric">###</a>3) Step two requires more than efficiency rhetoric</h3>
<p>Assertions that the approach is faster, cheaper, or more scalable without claim
language that concretely implements a technical improvement are unlikely to
establish an inventive concept, especially on a record limited to intrinsic
evidence and generalized expert opinions.</p>
<h3 id="4-avoid-field-of-use-crutches"><a class="heading-anchor" href="#4-avoid-field-of-use-crutches" aria-label="Link to this section: 4) Avoid field-of-use crutches:">###</a>4) Avoid field-of-use crutches:</h3>
<p>Limiting claims to a “technological environment” (streaming, wireless
rendering, event scheduling, network maps) is often treated as a new
environment for an otherwise generic technique and does not, by itself, prevent
an abstract-idea finding at Step One.</p>
]]></content><author><name>Noah K. Tilton</name></author><category term="federalcircuit"/><category term="subject-matter-eligibility"/><category term="101"/><summary type="html">GoTV Streaming, LLC v. Netflix, Inc., Nos. 2024-1669, 2024-1744 (Fed. Cir. Feb. 9, 2026)
On February 9, 2026, the U.S. Court of Appeals for the Federal Circuit reversed a judgment and jury damages award against Netflix, holding that the asserted claims of three related GoTV Streaming patents (U.S. Patent Nos. 8,478,245, 8,989,715, and 8,103,865) are patent-ineligible under 35 U.S.C. § 101. The court concluded the claims are directed to an abstract idea (using a generic template of specifications and then tailoring those specifications to a user device’s constraints using conventional server/ network operations) and do not recite an inventive concept sufficient to transform that idea into patent-eligible subject matter.</summary></entry><entry><title type="html">IPO Annual Meeting 2025 + San Diego Impressions</title><link href="https://blog.tilton.co/2025/09/15/IPO-2025.html" rel="alternate" type="text/html" title="IPO Annual Meeting 2025 + San Diego Impressions"/><published>2025-09-15T00:00:00-05:00</published><updated>2026-07-24T10:55:39-05:00</updated><id>https://blog.tilton.co/2025/09/15/IPO-2025</id><content type="html" xml:base="https://blog.tilton.co/2025/09/15/IPO-2025.html"><![CDATA[<div class="video-embed">
  <iframe src="https://www.youtube-nocookie.com/embed/d4XNWYM1Zhs" title="IPO 2025 San Diego timelapse" loading="lazy" allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture; web-share" referrerpolicy="strict-origin-when-cross-origin" allowfullscreen></iframe>
</div>

<p>IPO 2025 just wound down, and wow &hellip; what a time.  San Diego is a cool
place that I haven&rsquo;t been to since I was a wee lad &ndash; so it&rsquo;s as if I
was visiting for the first time.</p>
<figure class="blog-photo"><img src="/assets/img/koala.jpg" alt="Zoo" title="icky not panda" loading="lazy" decoding="async" width="1200"><figcaption>icky not panda</figcaption></figure>

<p>It&rsquo;s a bit weird that the entire place is cashless (seriously, you
cannot pass a bill almost anywhere unless you get off the beaten path).
That reminds me, I should take some pre-paid credit cards with me next
year.</p>
<figure class="blog-photo"><img src="/assets/img/lizard.jpg" alt="Zoo" title="lizard king" loading="lazy" decoding="async" width="1200"><figcaption>lizard king</figcaption></figure>

<p>It also takes some getting used to that every time you look up, you see a
military helicopter (or three) flying in formation, a nuclear-powered
carrier looming across the harbor, or a destroyer go trawling by.
Usually surrounded by a pack of jet skis.</p>
<figure class="blog-photo"><img src="/assets/img/destroyer.jpg" alt="destroyer" title="guided missile destroyer?" loading="lazy" decoding="async" width="1200"><figcaption>guided missile destroyer?</figcaption></figure>

<p>At the same time, the weather is great, and the whole place is dipped in
a SoCal vibe that&rsquo;s kind of hard to put your finger on, yet
unmistakable.  I could not live in California for reasons, but I&rsquo;d sure
like to visit again.</p>
<figure class="blog-photo"><img src="/assets/img/morning.jpg" alt="morning" title="funrun" loading="lazy" decoding="async" width="1200"><figcaption>funrun</figcaption></figure>

<p>As for the conference, the IPO annual meeting is as focused and
professional as it gets, bringing together many of the best IP minds
under one roof (which is more fun than it sounds like, promise).  I was
lucky to have several good meetings come together, both planned and
unplanned.  And I played pickleball for the first time ever, which
on its own made the trip worth it.</p>
]]></content><author><name>Noah K. Tilton</name></author><category term="travel"/><category term="workcation"/><category term="photo"/><category term="timelapse"/><category term="sandiego"/><summary type="html"> IPO 2025 just wound down, and wow … what a time. San Diego is a cool place that I haven’t been to since I was a wee lad – so it’s as if I was visiting for the first time.
icky not panda It’s a bit weird that the entire place is cashless (seriously, you cannot pass a bill almost anywhere unless you get off the beaten path). That reminds me, I should take some pre-paid credit cards with me next year.</summary></entry><entry><title type="html">Hello, world.</title><link href="https://blog.tilton.co/2025/09/11/hello-world.html" rel="alternate" type="text/html" title="Hello, world."/><published>2025-09-11T00:00:00-05:00</published><updated>2026-07-24T10:55:39-05:00</updated><id>https://blog.tilton.co/2025/09/11/hello-world</id><content type="html" xml:base="https://blog.tilton.co/2025/09/11/hello-world.html">&lt;p>Kicking off this blog as a space for writing that doesn&amp;rsquo;t fit anywhere
else.  The views expressed herein are my personal views and do not
necessarily reflect those of anyone else.  See footer for the full
Disclaimer.&lt;/p>
</content><author><name>Noah K. Tilton</name></author><summary type="html">Kicking off this blog as a space for writing that doesn’t fit anywhere else. The views expressed herein are my personal views and do not necessarily reflect those of anyone else. See footer for the full Disclaimer.</summary></entry></feed>